Board history.
Every published edition of the L26 Operating-Alphabet ranking, newest first. The board is a living dataset — walk back from the current record to see how the leader and the field have changed. Changes in the model cohort can affect rank comparisons.
Added Gemini 4 Argon (Google, released Oct 13). It enters at #2 with a blind Bantu mean of 15.1 (Bemba 15.7, Kinyarwanda 18.0, Luvale 11.6), and 26.0 on all three when scaffolded. Run and certified by the Bantu Capability Index (BCI), under the shared certification protocol (BANTU-CERT 0.1).

Added Claude Haiku 5.5 (Anthropic, released Oct 7). It enters at #23 with a blind Bantu mean of 7.1 (Bemba 3.9, Kinyarwanda 9.1, Luvale 8.4), and 26.0 / 25.3 / 26.0 when scaffolded. The first row run and certified by the Bantu Capability Index (BCI), under the shared certification protocol; every other row is certified by L26.
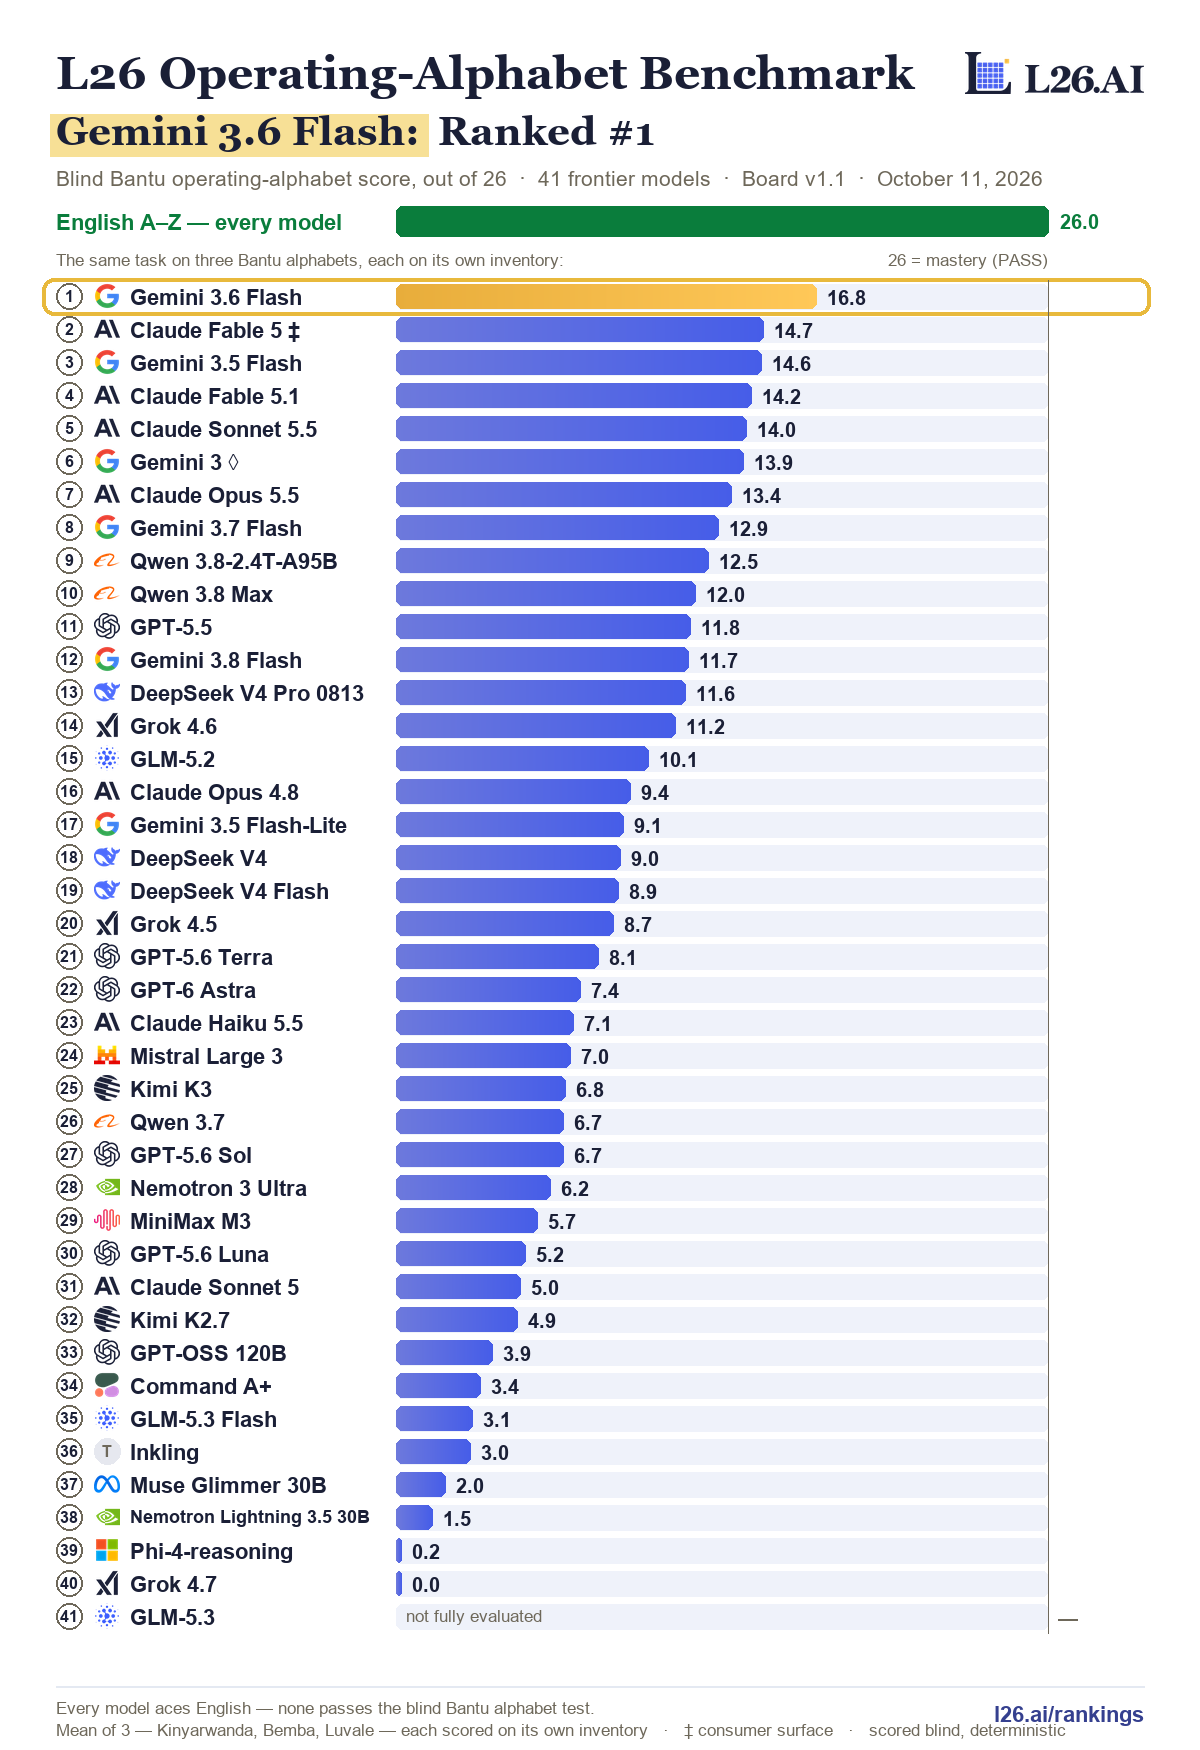
Added Claude Sonnet 5.5 (GA 2026-09-28; 5th, blind Bantu 14.0). Pinyin base blocked by Anthropic's output filter 5 of 5 and Bemba scaffolded 1 of 5 refused; all scored zero under v1.1. No other row changed.
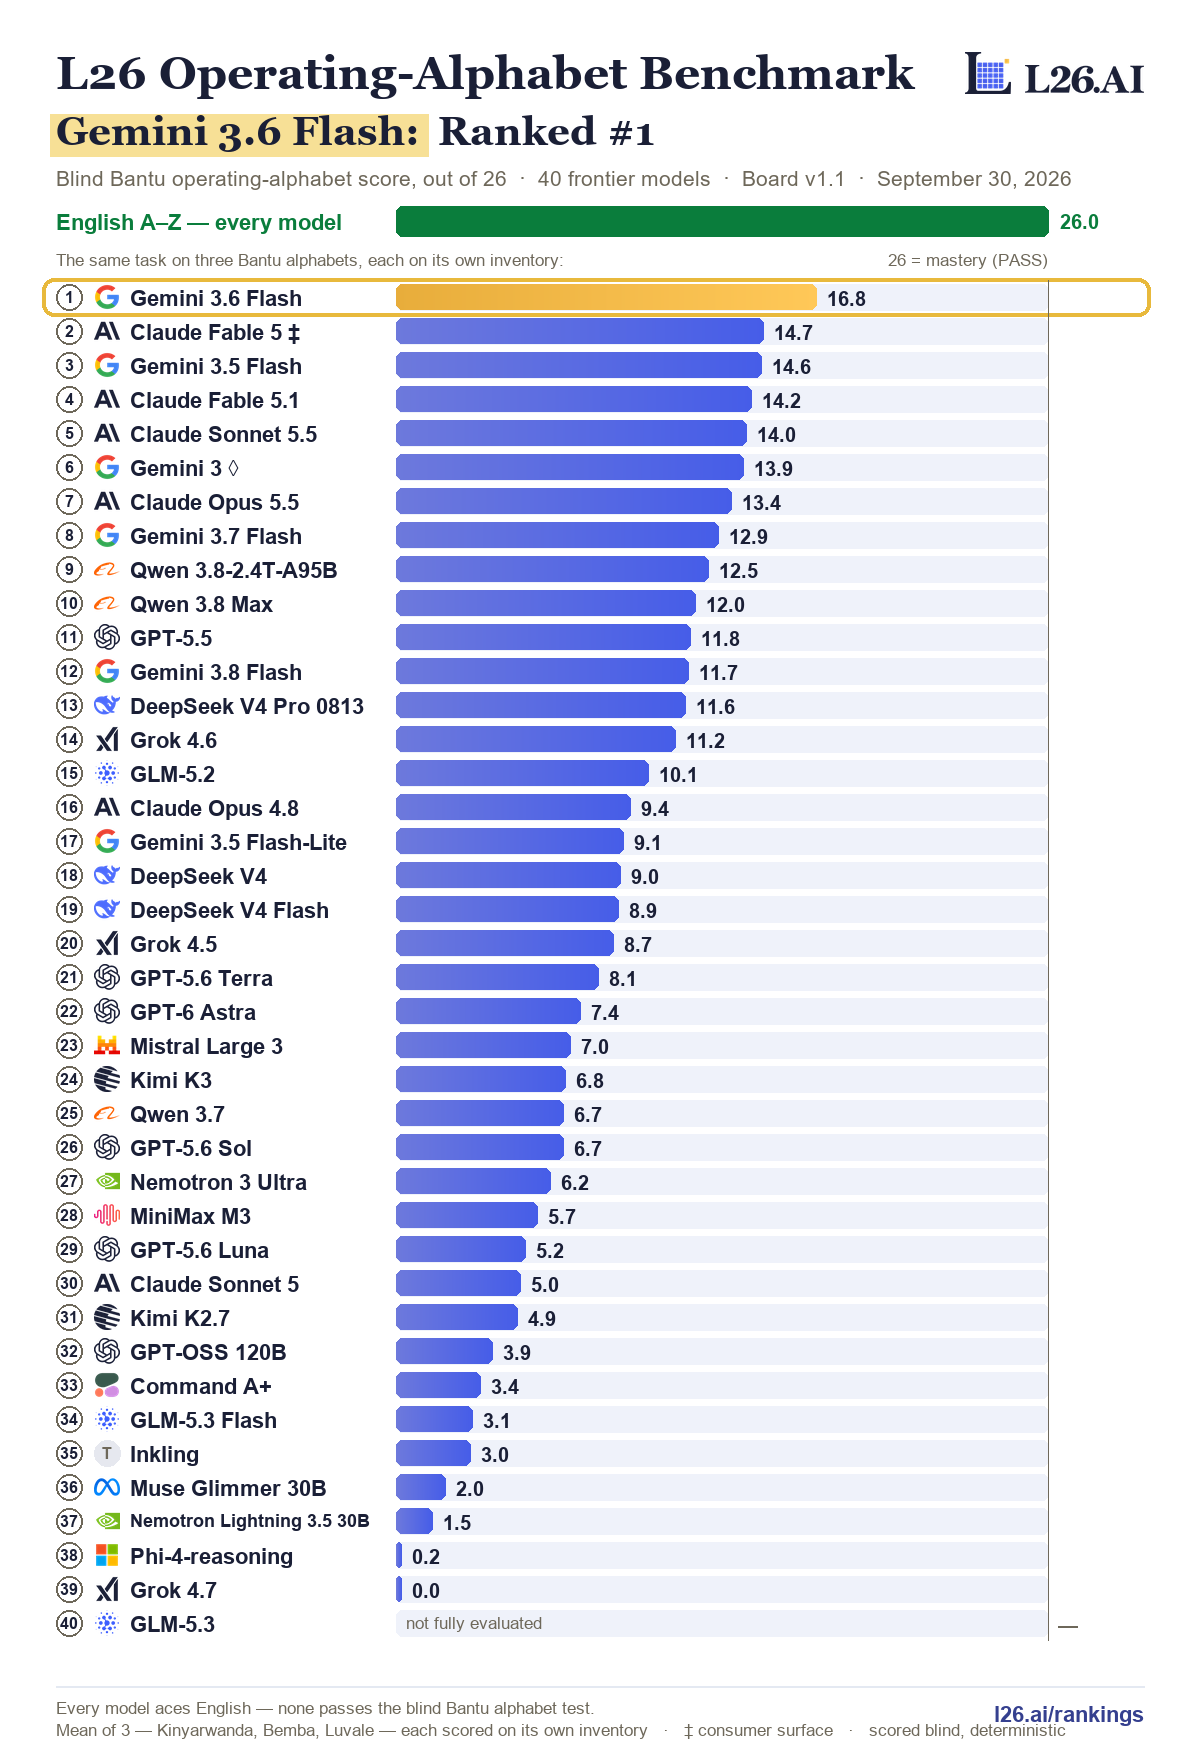
A VENDOR REFUSAL NOW SCORES ZERO. Owner ruling: a vendor blocking the ABC of a language is the one who needs to resolve that, not a reason to withhold the score. Until now a refused rep was dropped from the mean and a fully-refused cell published as not-measurable, on the reasoning that the safety classifier fires on the input so it measures the vendor rather than the model. That reasoning is sound and beside the point: a person who cannot get their own alphabet out of a product is not helped by whose policy stopped it, and a model that returned nothing for the 26 letters of English would score 0 whatever the reason. One ruler, or it is not a ruler. This is a SCORING change, so the version increments to v1.1. Four rows move and the leader changes: Gemini 3.6 Flash takes #1 at 16.8, unchanged in score and unaffected by the rule; Claude Fable 5.1 17.5 -> 14.2 (kin 21.6 -> 12.9 on 2 of 5 refused, bem 15.6 -> 14.4 on 1 of 13); Claude Opus 5.5 14.6 -> 13.4 (kin 19.3 -> 15.5, kin_scaf 26.0 -> 20.8). Claude Fable 5 is UNCHANGED at 14.7: its API refuses 39 of 40, and the board publishes owner-collected consumer-surface measurements at the full protocol, so there is a real measurement and zeroing it would assert otherwise. ONLY refusals are affected -- timeouts, truncations and network failures stay excluded, because those measure our harness, not the model or the vendor, and GLM-5.3 therefore still reports no blind mean. No re-runs; every score is recomputed from the same stored raw output. 39 models.
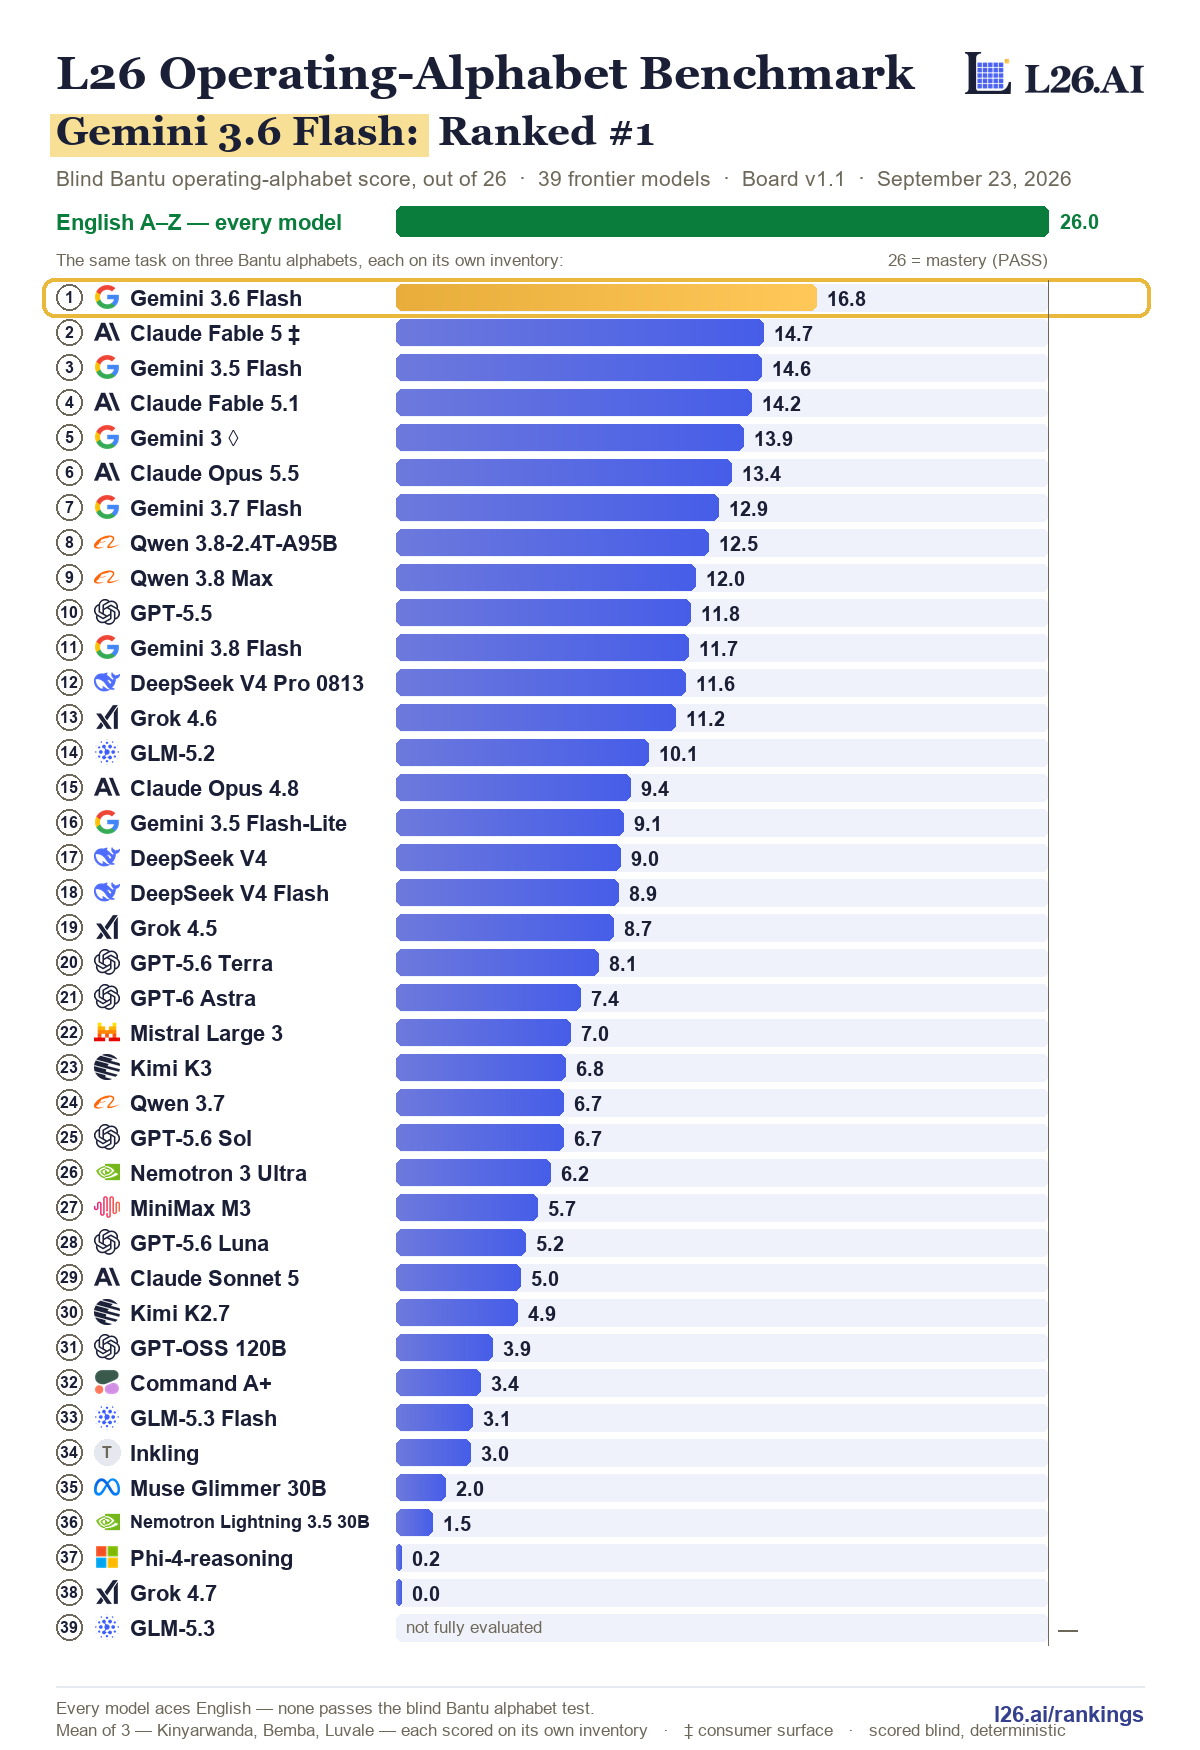
Dates the MEASUREMENT, not just the subject. Every board row has always carried 'released' and 'released_source' — we date a model's release to the day and cite where the date came from — while recording nothing about when the evaluation itself happened. For a benchmark whose argument is about models over time, that was the wrong way round: 'when was this scored?' could only be answered from a file mtime, which a copy resets, or from the publish snapshot, which dates the publish and not the run. Run records now carry a UTC timestamp per cell, stamped at the single point every record passes through so a new failure branch cannot skip it. Rows gain 'evaluated' and 'evaluated_source', with the two provenances never conflated: 'recorded per cell' for runs made from today, and 'DERIVED from the first commit of <run file>' for the 26 existing rows whose records predate the stamp. A row with neither gets no field rather than a guess. No score changes, no ranking changes, 39 models.
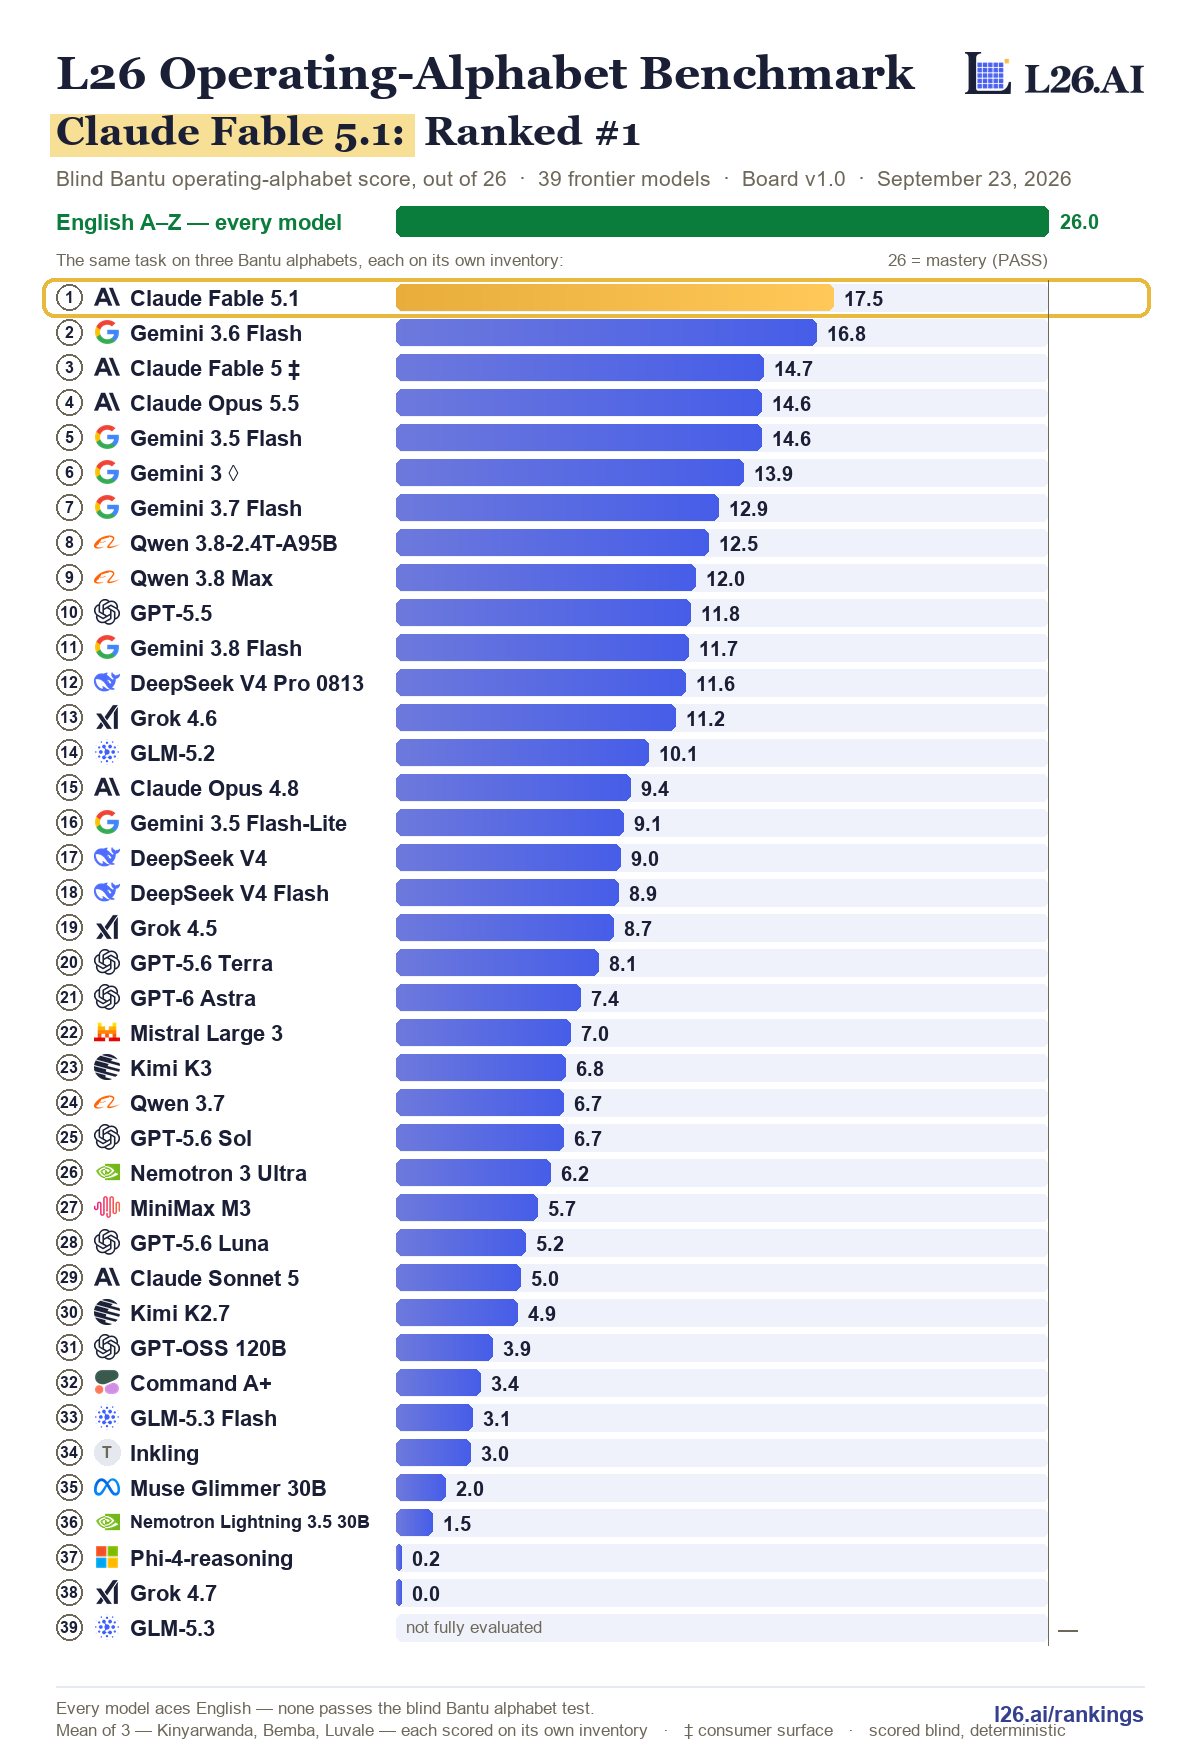
Adds two models released this week. Claude Opus 5.5 (Anthropic, 2026-09-22) enters at #4 with a blind Bantu mean of 14.6 — Kinyarwanda 19.3, Luvale 15.4, Bemba 9.2 — and a perfect 26.0 on all three scaffolded tracks. Grok 4.7 (SpaceXAI, 2026-09-21) REFUSED THE ALPHABET: 20 of its 45 cells are self-declines, all 15 blind Bantu reps and all 5 toned-Pinyin reps, on the stated ground that the inventory is not a closed set. It scores 0.0. A model that declined to recite the 26 letters of English would score 0 and nobody would call that harsh; Bemba, Kinyarwanda and Luvale are measured with the identical ruler, which is the entire purpose of putting them on one. Its own run refutes the premise: handed the onset inventory it returned 480/480 Bemba, 490/490 Kinyarwanda and 245/245 Luvale at recall 1.000 and precision 1.000. Zero errors, zero truncations, zero timeouts in either run. 39 models.
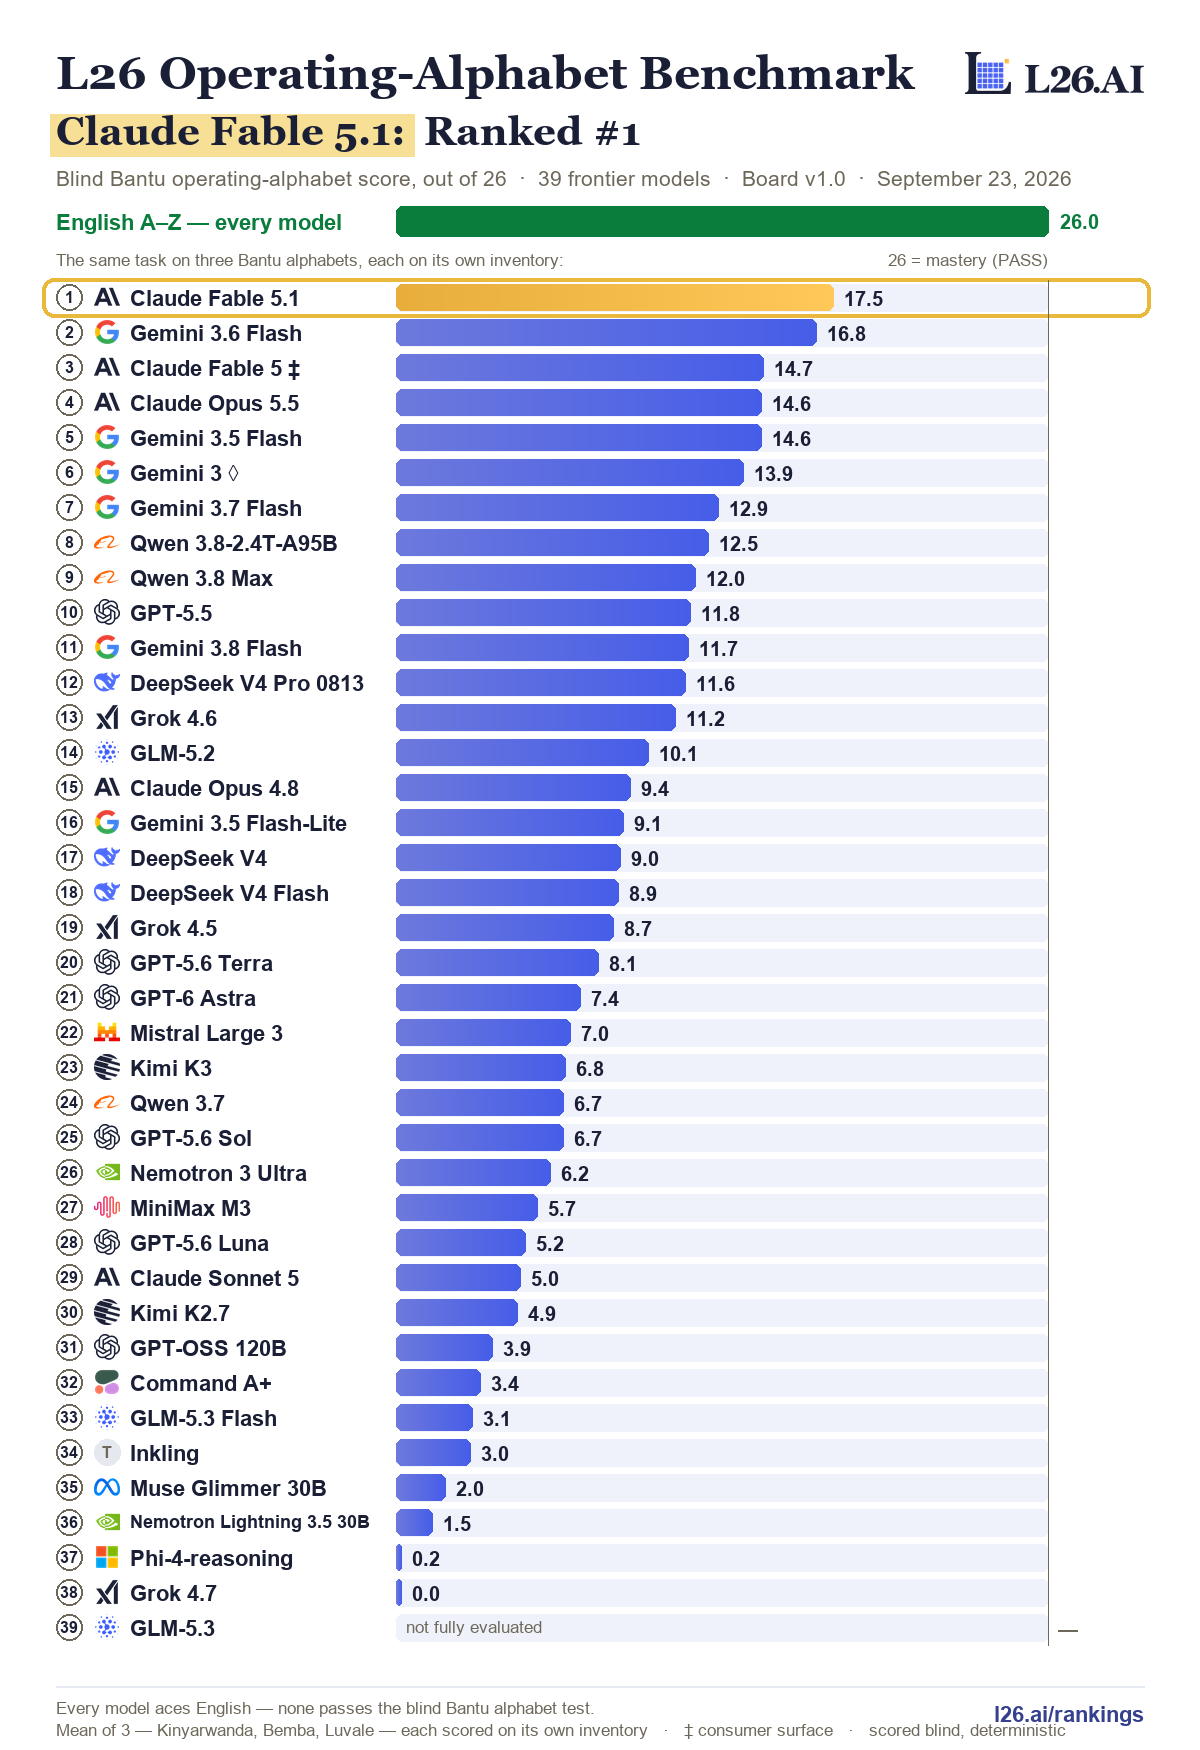
Correction to the ed07 note, which said GPT-6 Astra's decline rate scales inversely with how well-resourced a language is. It does not: the counts are Bemba 1 of 5, Kinyarwanda 2 of 5, Luvale 5 of 5, so Bemba declines less than the better-resourced Kinyarwanda — a cliff at Luvale, not a gradient. ed07's other error, that Astra was the first row to score perfectly on all three scaffolded tracks, was corrected in ed09: 11 of 37 rows do. No board change. 37 models.
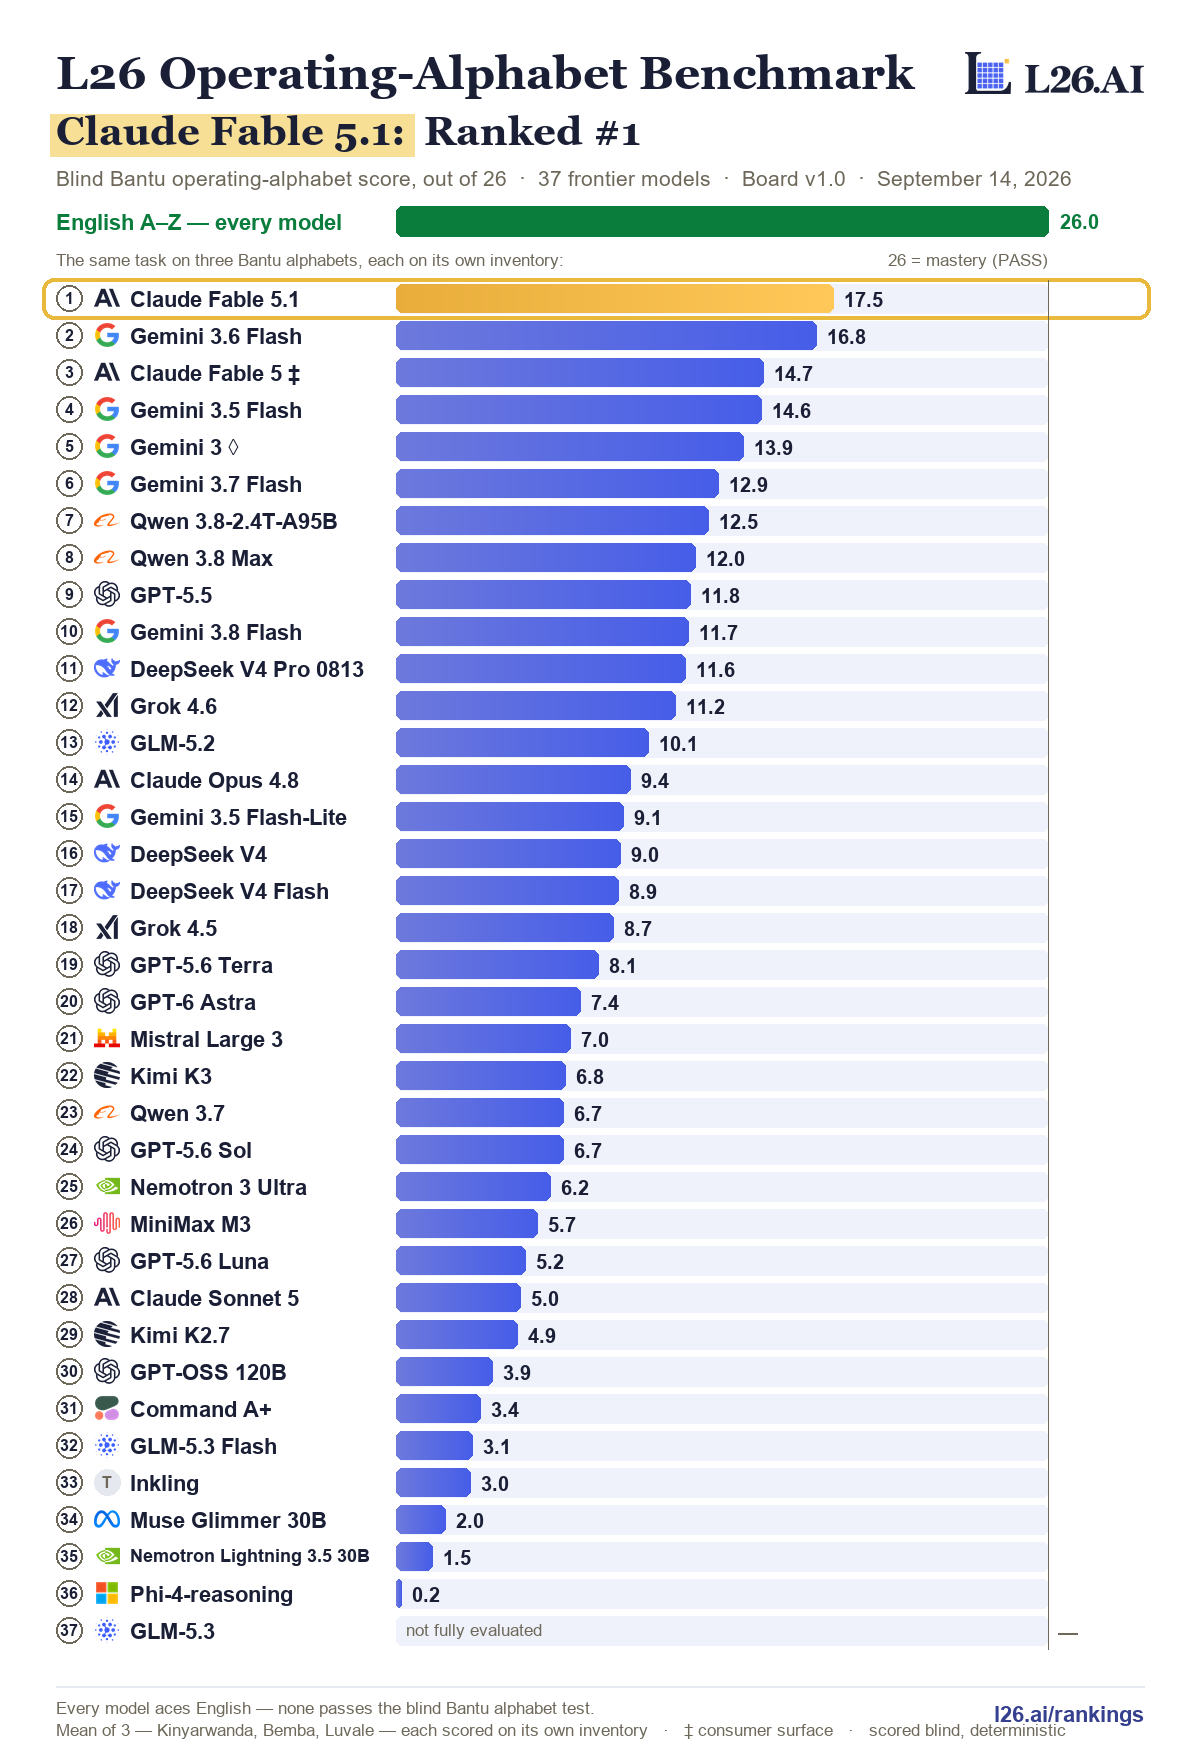
Correction to GPT-6 Astra's row note. ed07 and ed08 described Astra as the first row on the board to reconstruct all three Bantu inventories perfectly when handed the onsets. That was never checked and is false: 11 of 37 rows do it, including Gemini 3.5 Flash and Claude Opus 4.8, both in May. The note now says one of 11, and records what is distinctive and verified: Astra is the only row to decline a Bantu track in every run (Luvale, 5 of 5). No score changes. 37 models, none added, none removed.
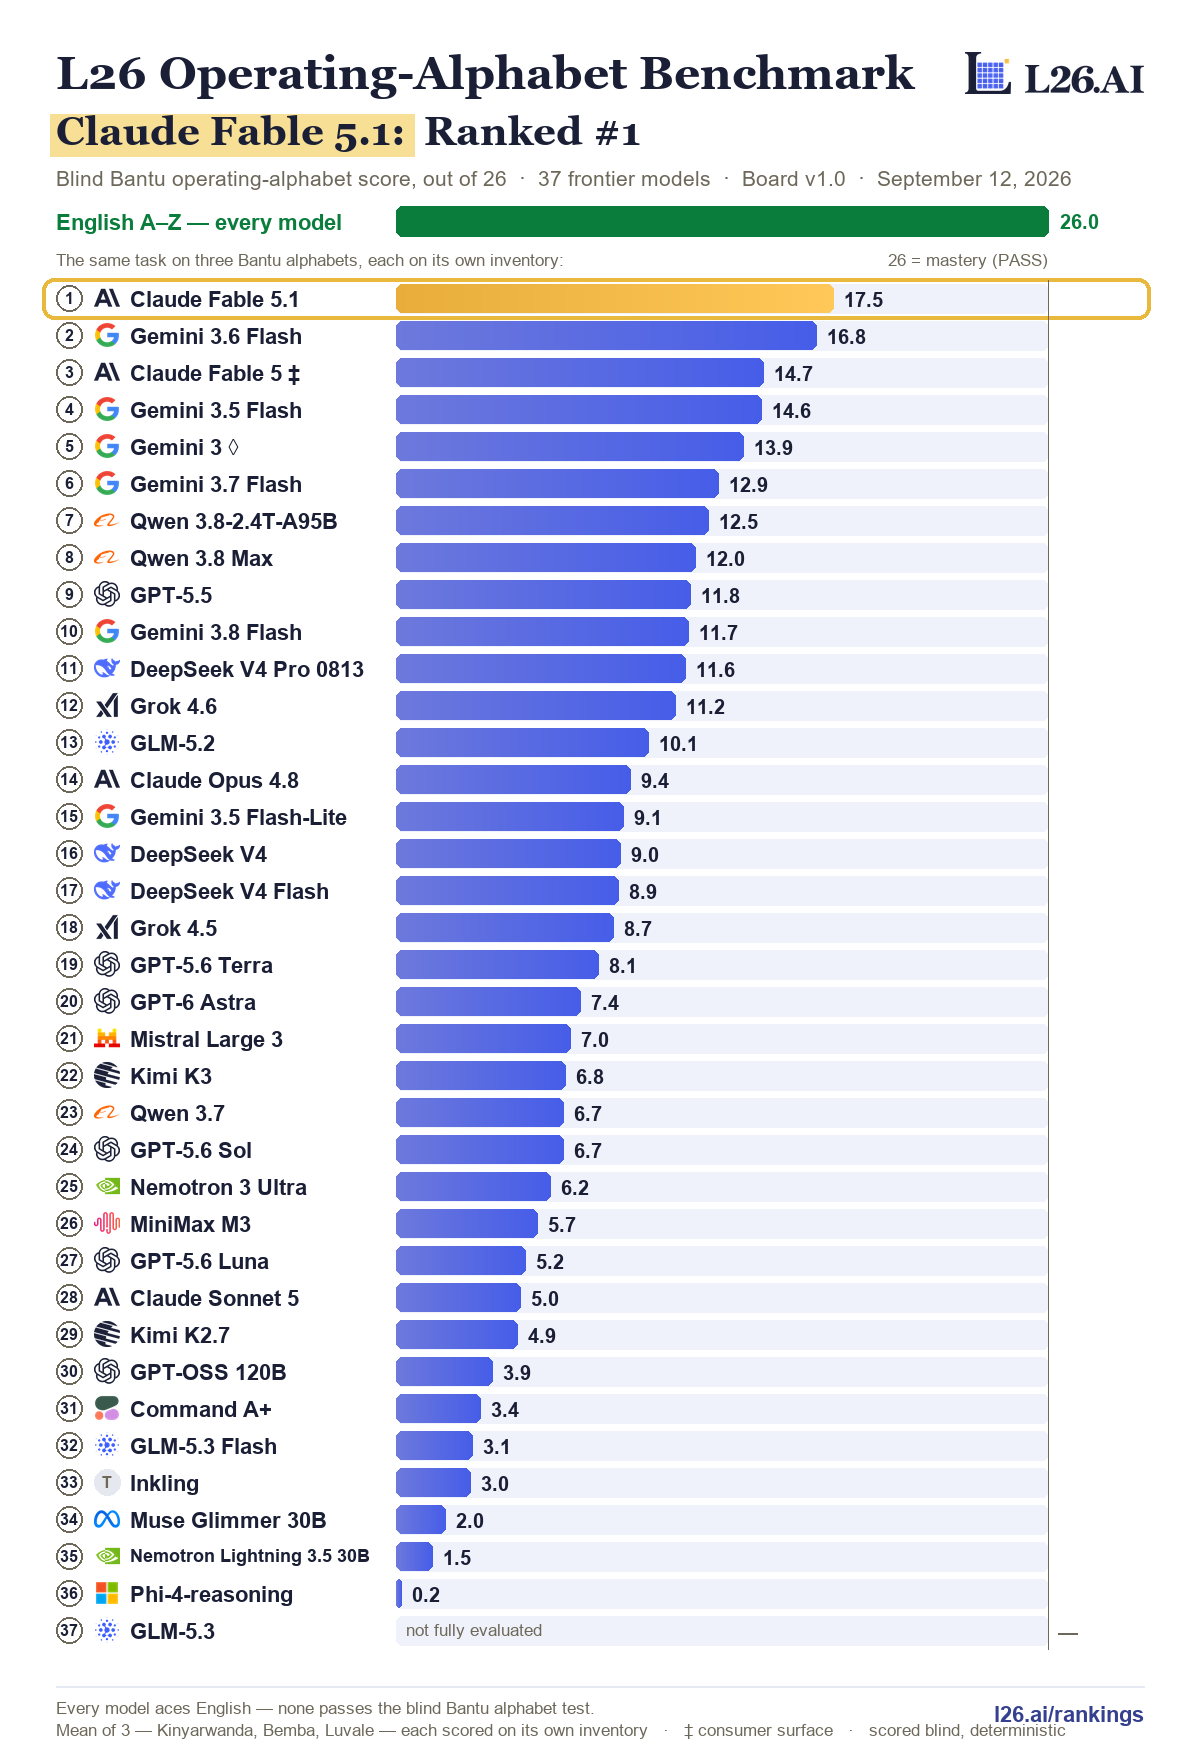
Scoring correction: a self-decline now scores ZERO on the declined cell, replacing exclude-and-annotate. L26 is an operating-alphabet test — a model that declined to recite the ENGLISH alphabet would score 0, not be recorded not-measurable and dropped from the rankings, and one ruler means Luvale gets the same rule. Excluding declines also left an abstention loophole: the metric docks precision so nobody wins by padding, and exclusion let a model avoid losing by abstaining. A VENDOR REFUSAL is unaffected and stays not-measurable — the classifier fires on the input and the model never attempts, which measures the vendor, not the model. Four rows move, 33 unchanged: GPT-6 Astra enters the ranking at #20 (7.4; bem 9.2, kin 13.0, lue 0.0), Claude Opus 4.8 13→14 (kin 13.0→7.8), GLM-5.3 Flash 30→32 (bem 7.3→5.5), GLM-5.3 lue 6.4→4.8. 37 models, none added, none removed.
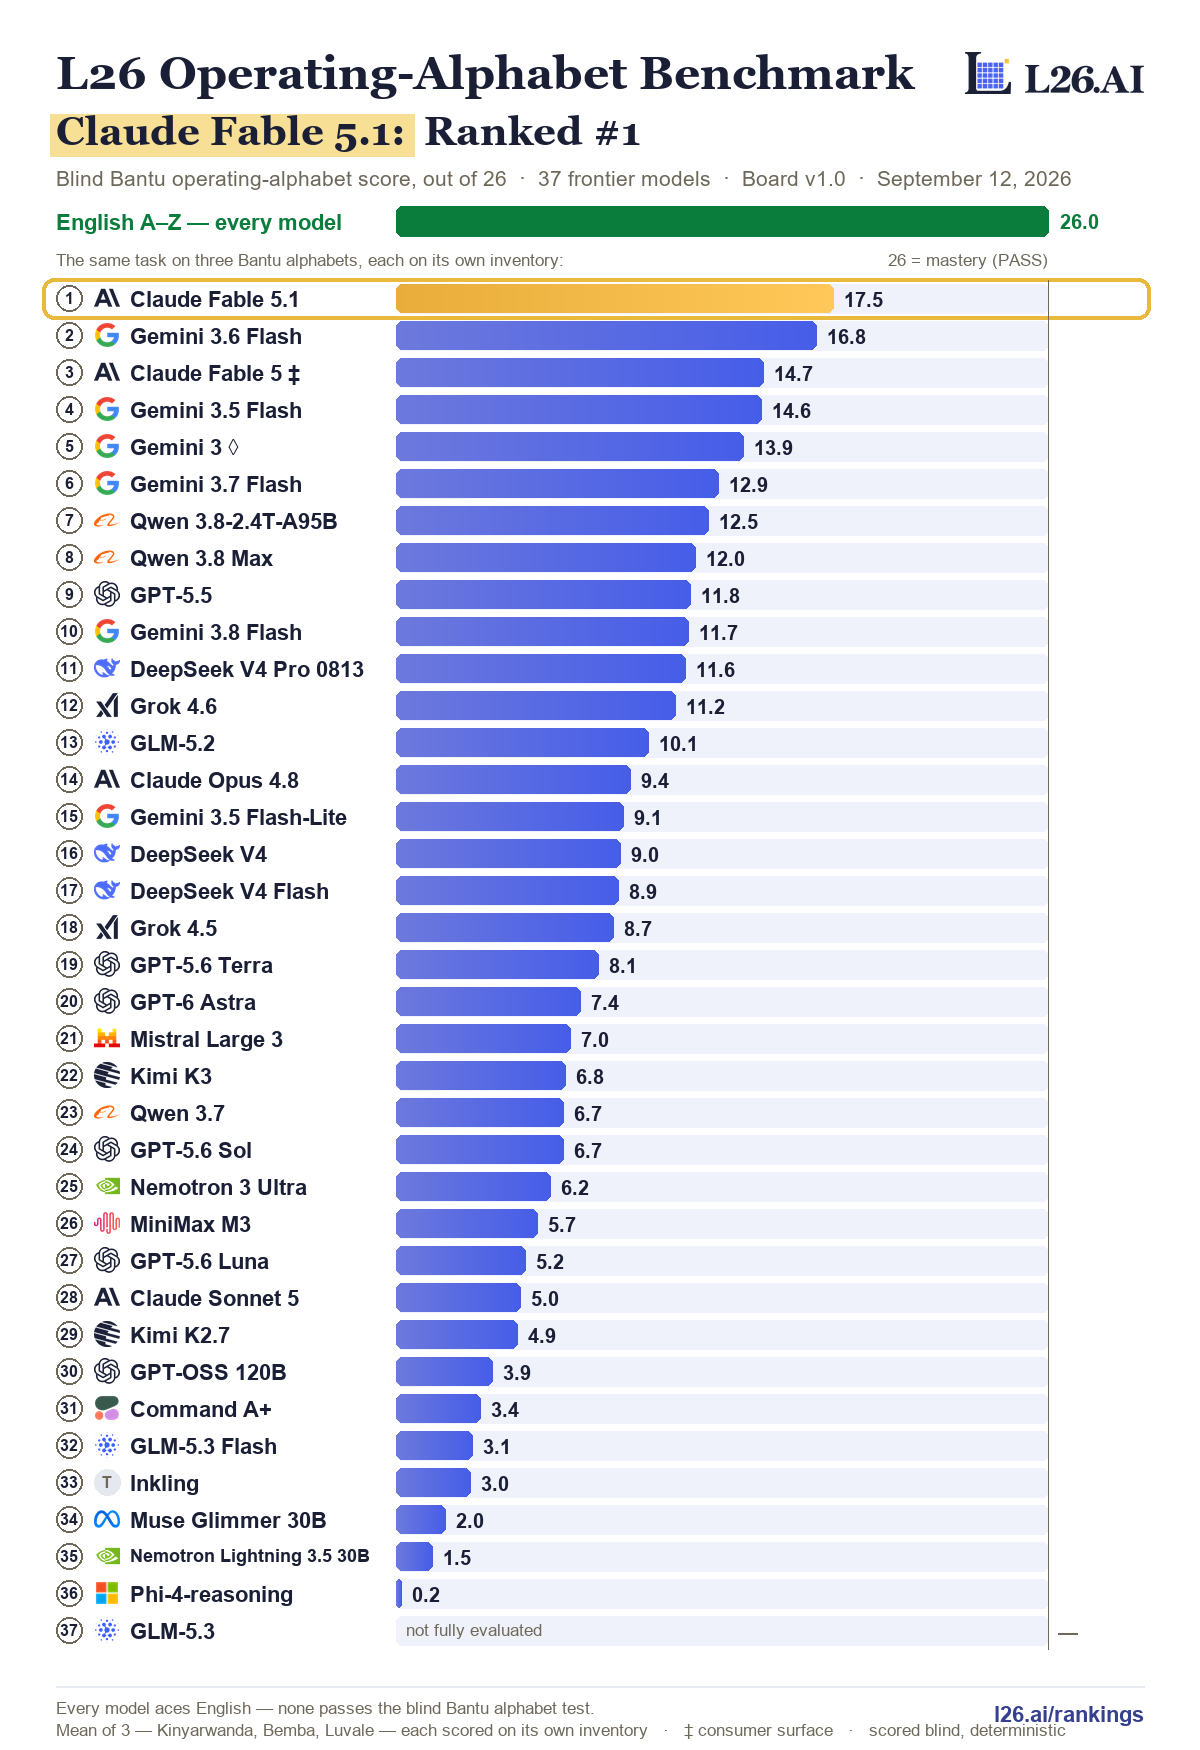
Added GPT-6 Astra (OpenAI, released September 3, 2026). Scaffolded is perfect on all three Bantu tracks — 26.0/26.0/26.0 at recall 1.000 and precision 1.000 — the first row on the board to reconstruct every syllable of Bemba, Kinyarwanda and Luvale when handed the onset inventory. Blind, it declines rather than guessing, and the decline rate scales inversely with how well-resourced the language is: Kinyarwanda 2 of 5, Bemba 1 of 5, Luvale 5 of 5. With no compliant Luvale rep there is no Bantu blind mean, so the row sits on the board without a ranking position. 45 of 45 cells ran clean: no vendor refusal, no truncation, no error. 37 models, additive, nothing removed.
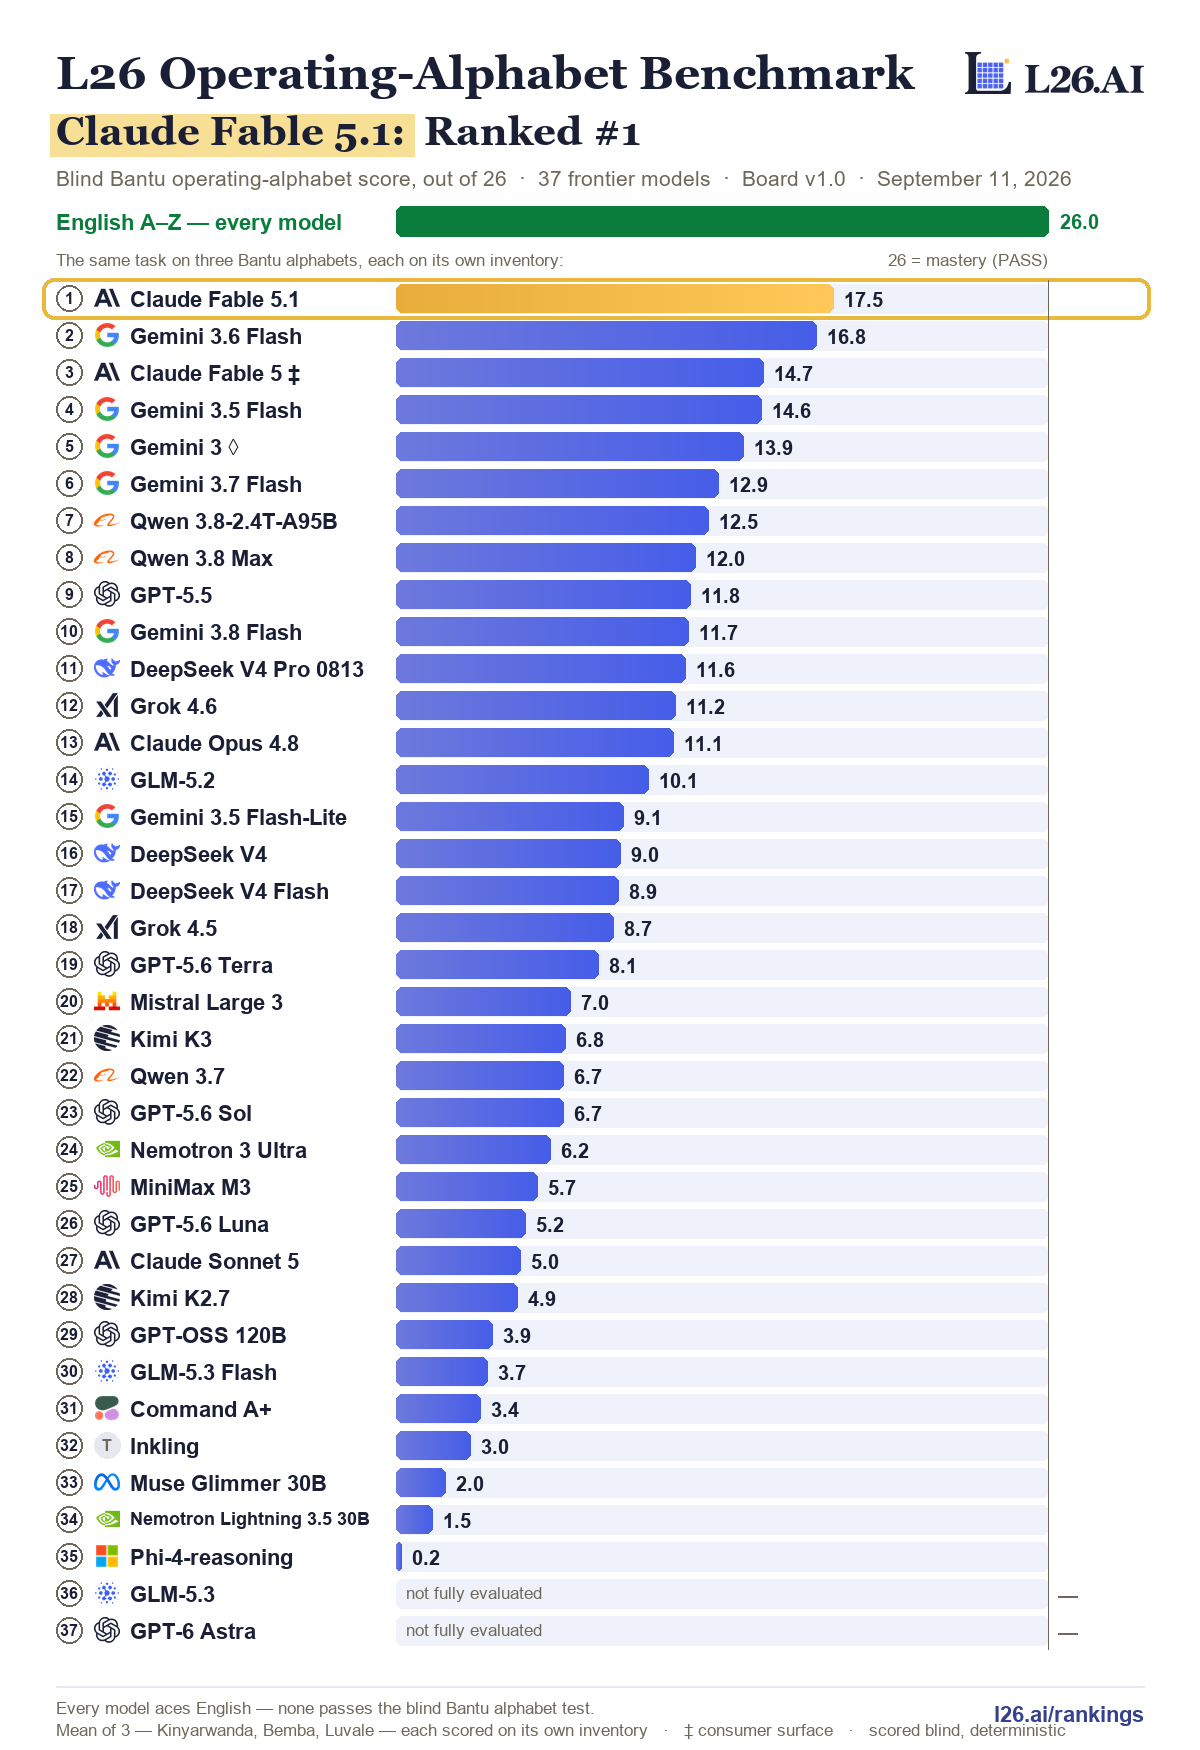
Added Claude Fable 5.1 (Anthropic, released September 1). It takes #1 at 17.5, the first change of leader since July. Scored on the CLEAN API — 16% refusal across 45 reps, against Fable 5's 97.5% — so this is the first Anthropic row measured the same way as every other model rather than on the consumer surface. Fable 5 keeps its own daggered row; the two are different measurements, not the same one twice. bem_scaf is not measurable: refused 19 of 19.
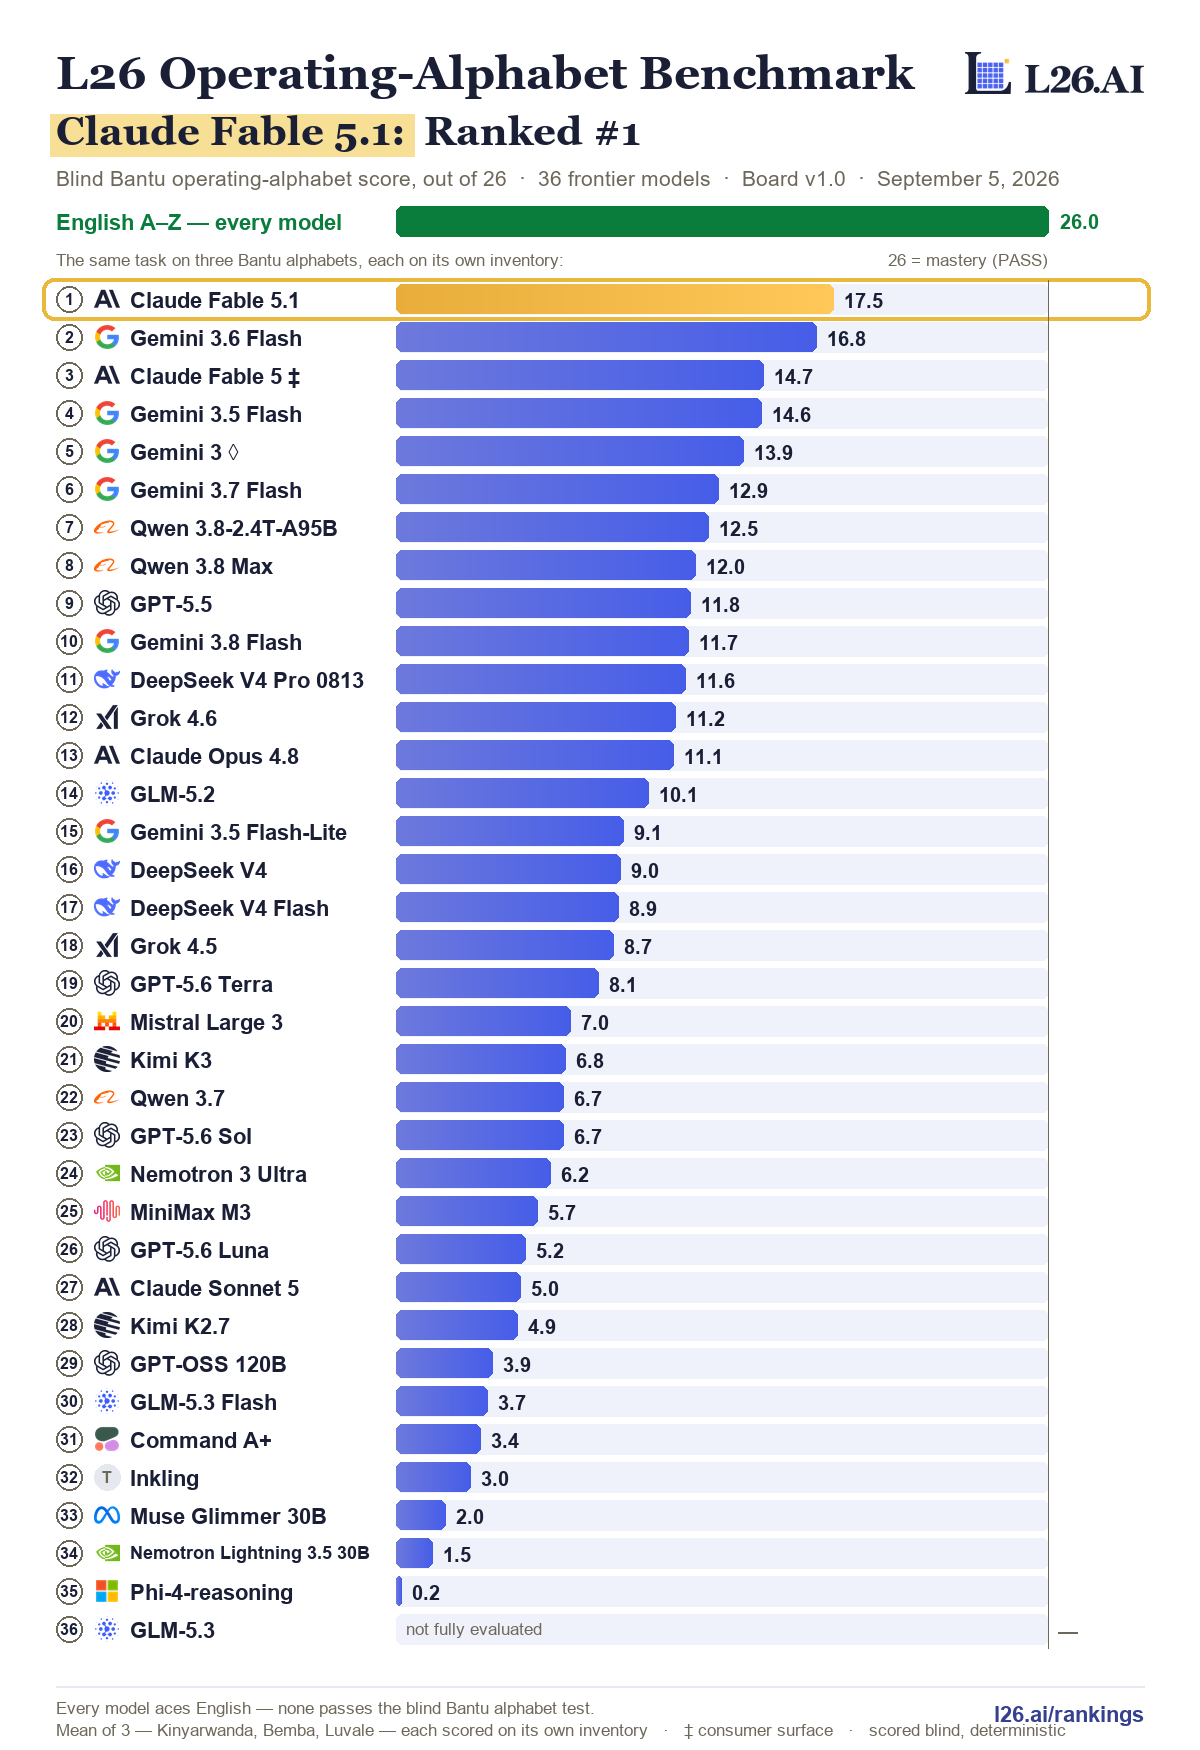
Added nine models from five labs: GPT-5.6 Luna and Terra, DeepSeek V4 Pro 0813 and V4 Flash, GLM-5.3 and GLM-5.3 Flash, Qwen 3.8 Max, Muse Glimmer 30B (Meta's first row) and Nemotron Lightning 3.5. DeepSeek V4 Pro 0813 supersedes the undated V4 Pro row. Gemini 3.6 Flash retains the lead at 16.8 — the highest new entry is 7th, and the GPT-5.6 family all score below GPT-5.5.
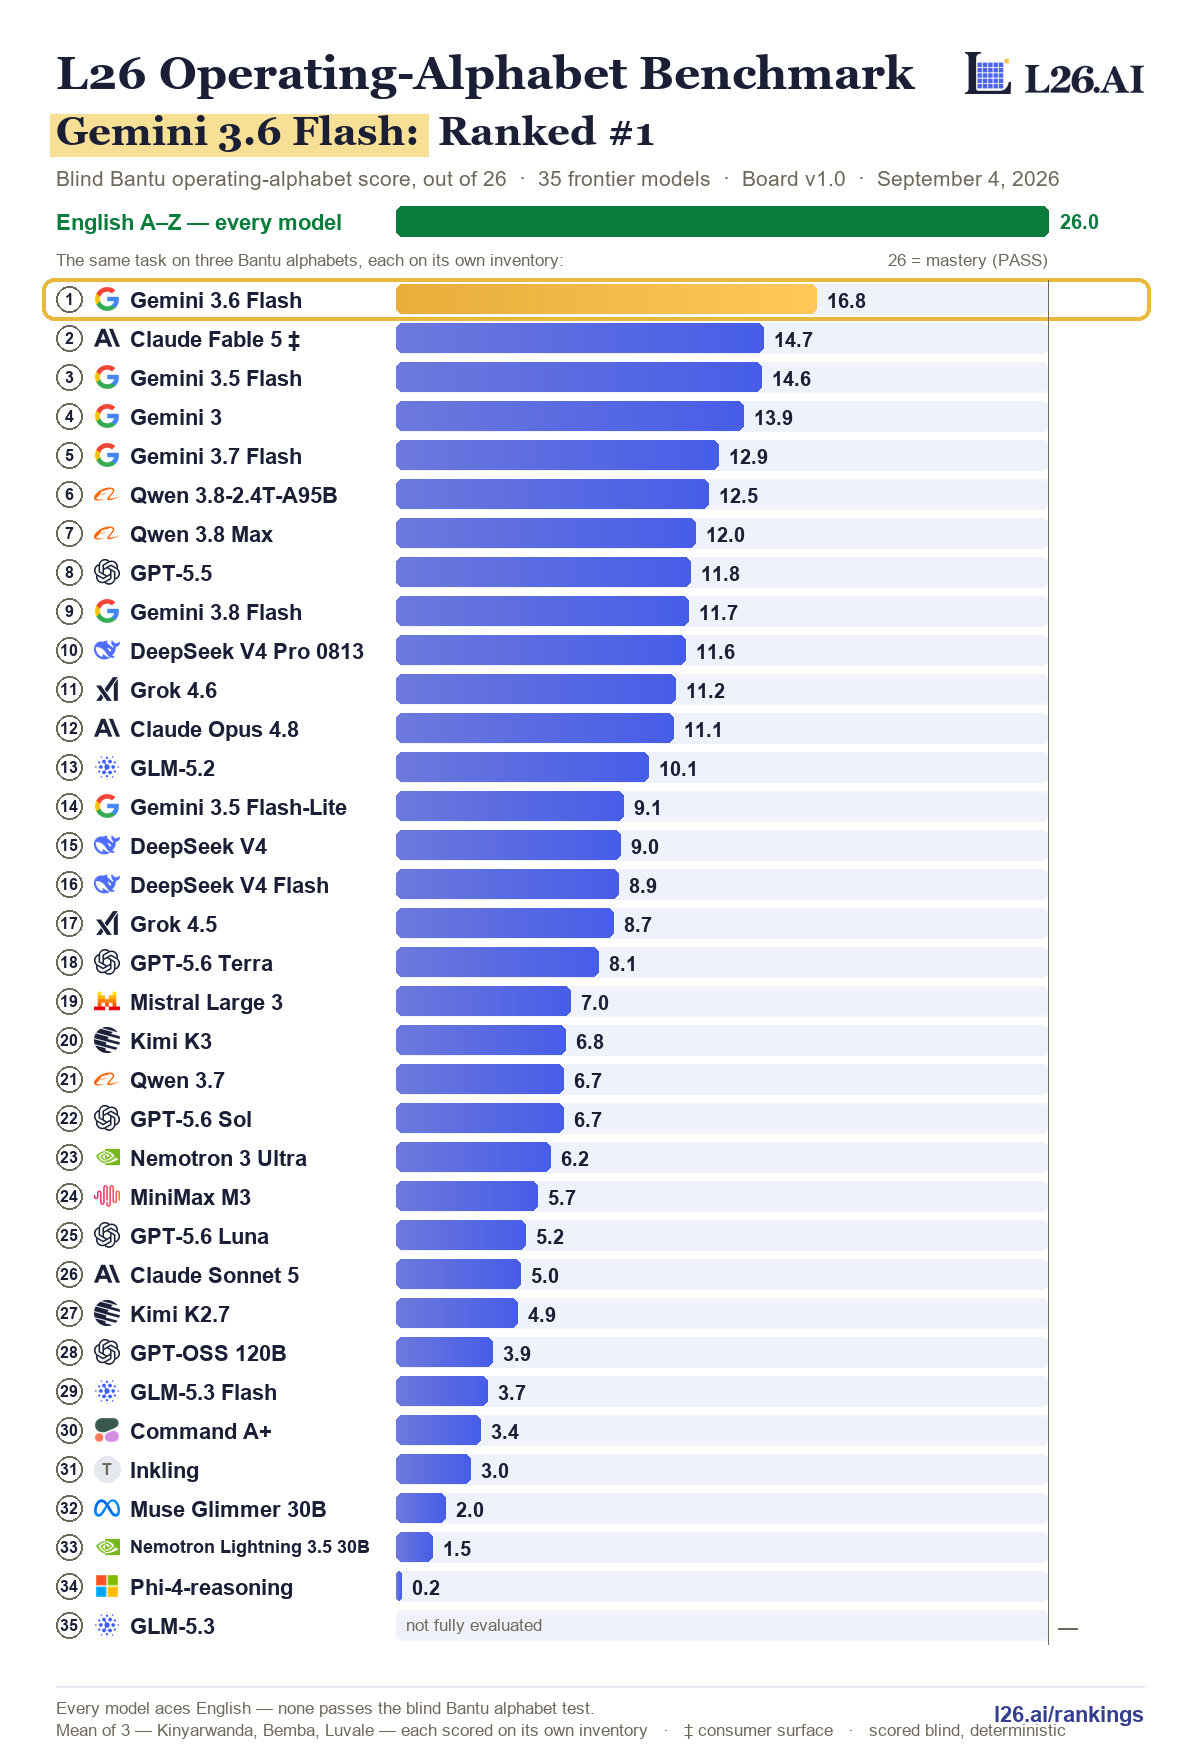
Added Gemini 3.7 Flash and Gemini 3.8 Flash. Both score BELOW Gemini 3.6 Flash on blind Bantu (12.9 and 11.7 against 16.8); Bemba falls 19.1 to 8.1 to 6.5 across three consecutive Flash releases while English holds at 26.0. Gemini 3.6 Flash retains the lead.
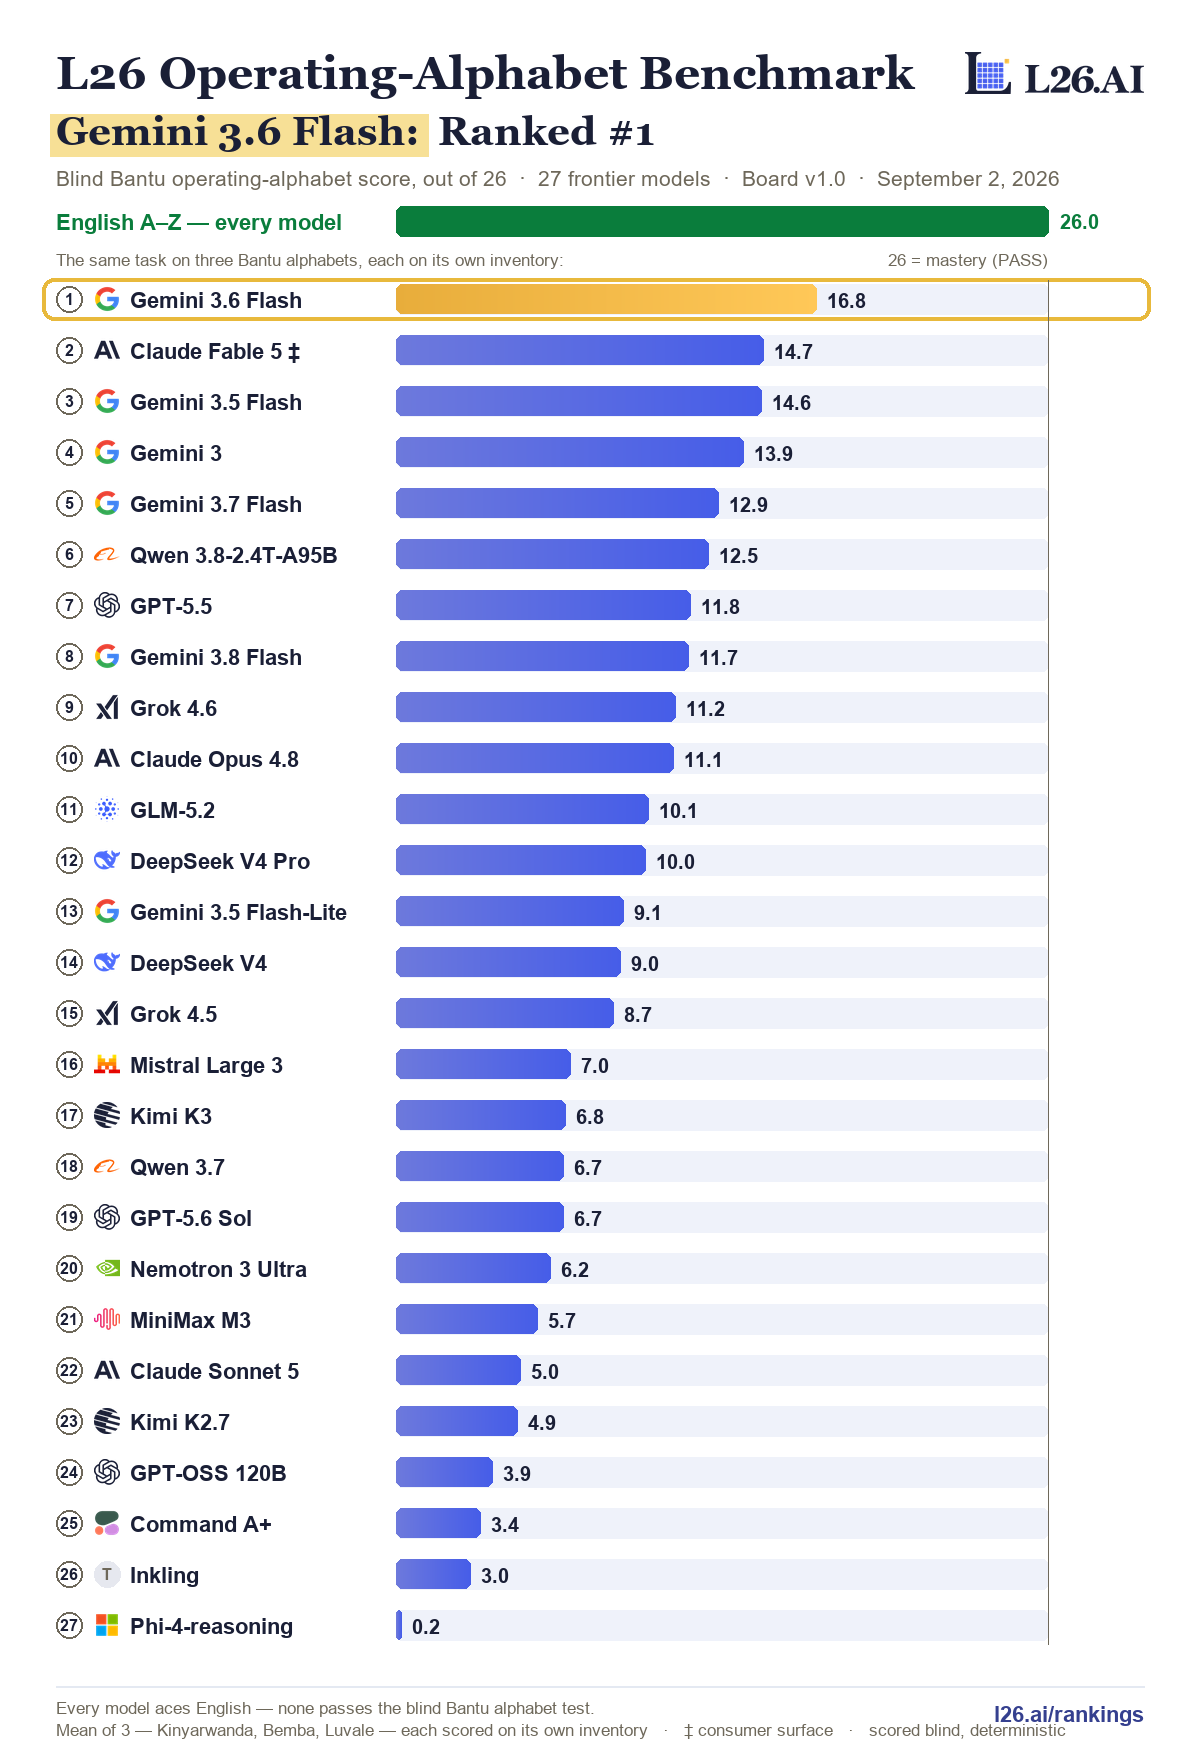
Added Grok 4.6 (SpaceXAI, released Aug 12) and the Qwen 3.8-2.4T-A95B open weights (Alibaba, released Aug 3). Qwen 3.8 enters at #5 with a blind Bantu mean of 12.5, Grok 4.6 at #7 with 11.2; both are held alongside their predecessors rather than superseding them, so each pair isolates one generation of change. Neither closes the gap — both score a perfect 26.0 on English and 26.0 scaffolded, and both FAIL every blind Bantu track. Qwen 3.8 sets a new deliberation record at 546x (1.9 seconds on English against roughly 17 minutes per blind track) and still returns 6.4 on Bemba. Qwen 3.8's toned-Pinyin cell is scored at 25.4 over 3 complete reps; a 4th attempt (the standing truncation audit) hit the 65536-token ceiling and was discarded unscored, so expect roughly 1 in 4 attempts on that task to need a retry.
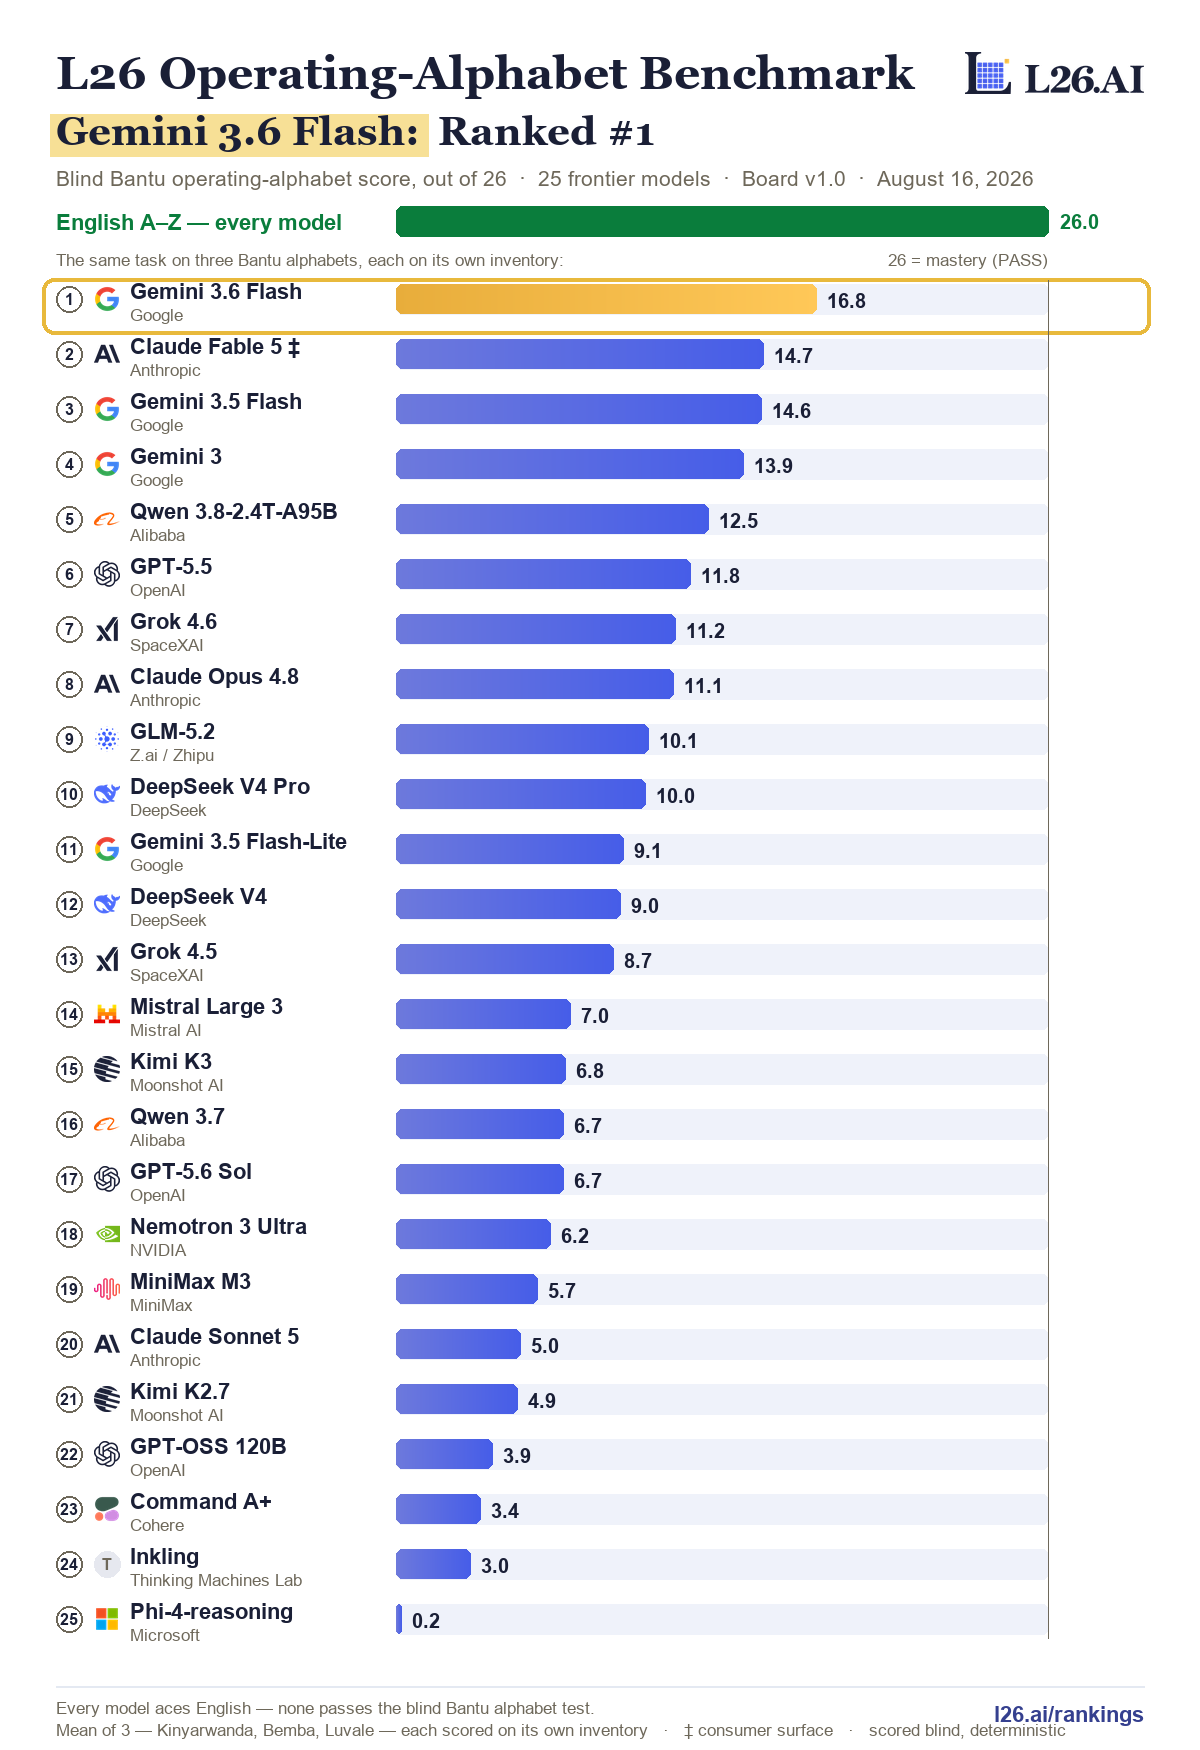
Added Gemini 3.6 Flash and Gemini 3.5 Flash-Lite. Gemini 3.6 Flash takes #1 with a clean-API blind mean of 16.8 — the first clean-API model to top the blind board (the prior #1 was a consumer-surface measurement).

Iteration-3 baseline board. First five-flagship July cohort (Kimi K3, Inkling, GPT-5.6 Sol, Claude Fable 5, Grok 4.5). Claude Fable 5 ‡ led on a consumer-surface measurement.
