Archived editionv1.0 · rev 4September 2, 2026 · 27 models← NewerOlder →Current board →
L26 OPERATING-ALPHABET BENCHMARK · ARCHIVED EDITION

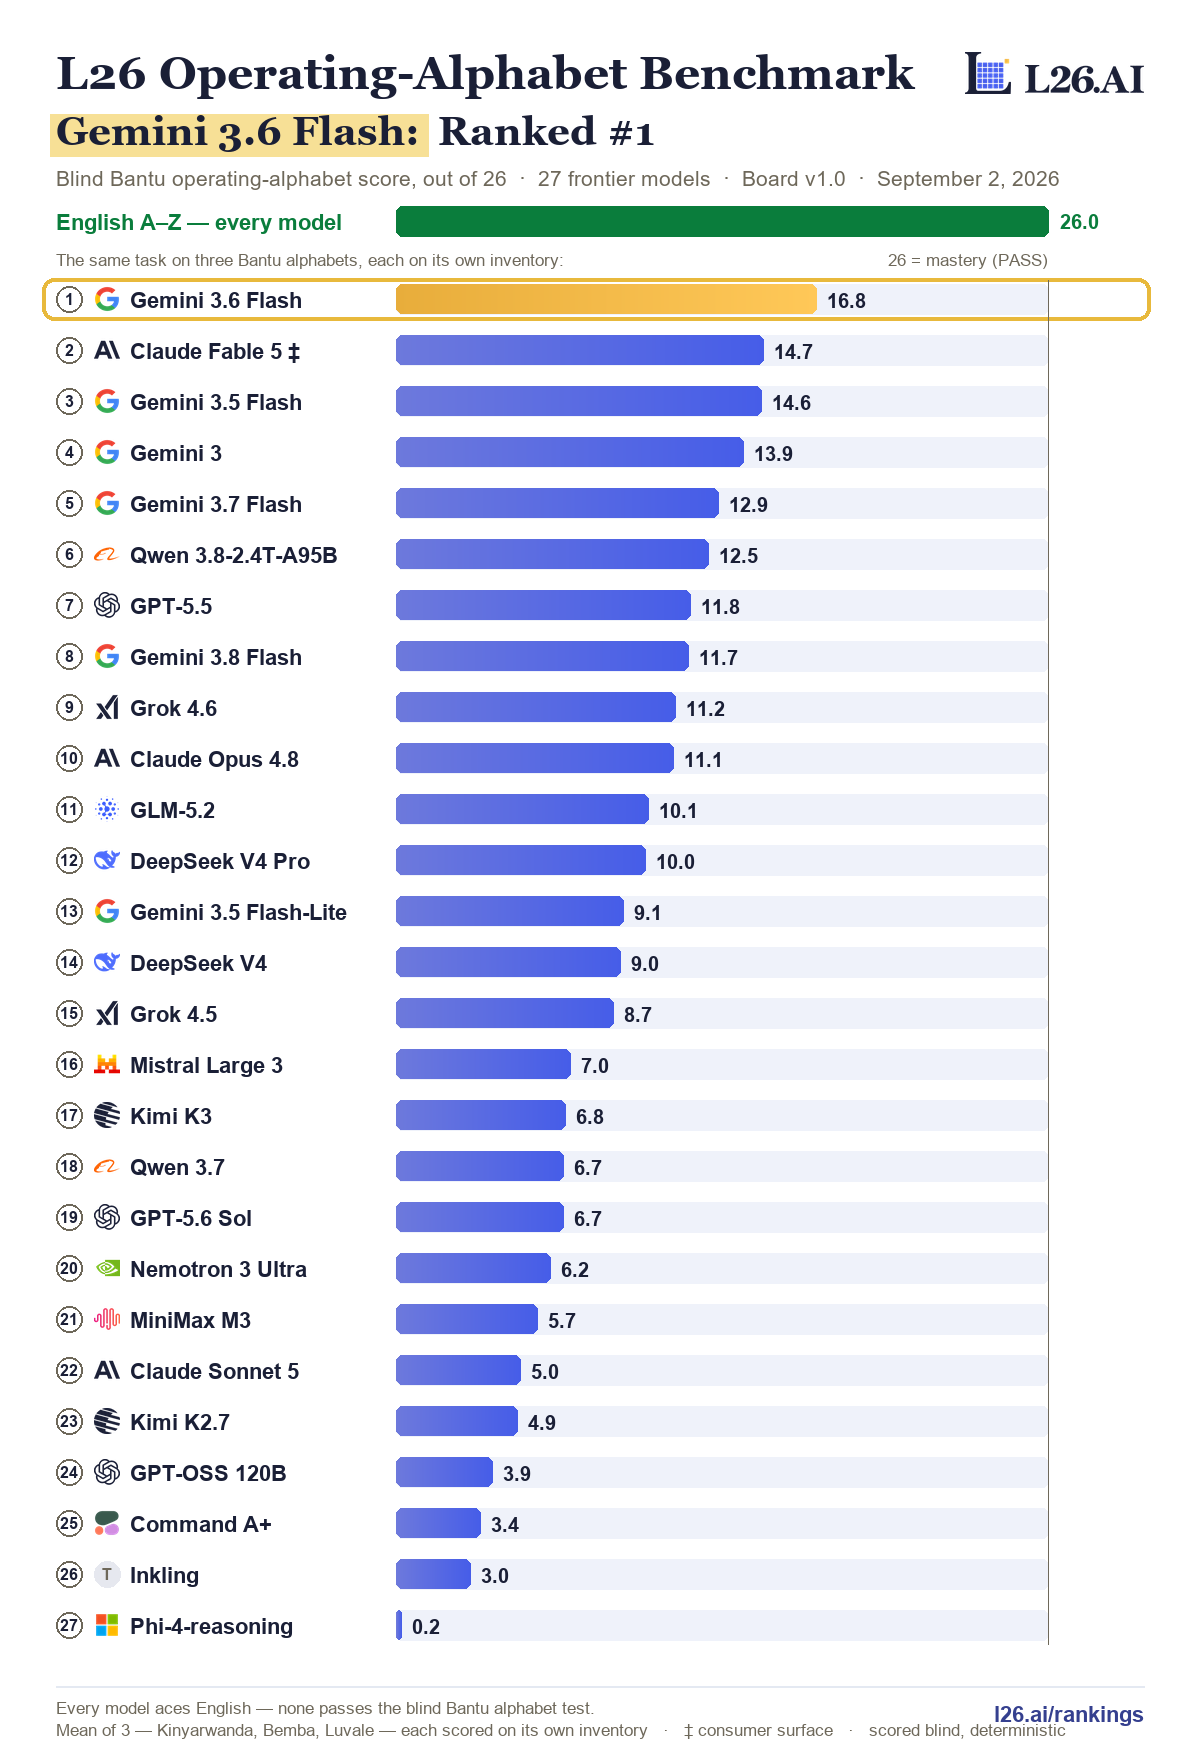
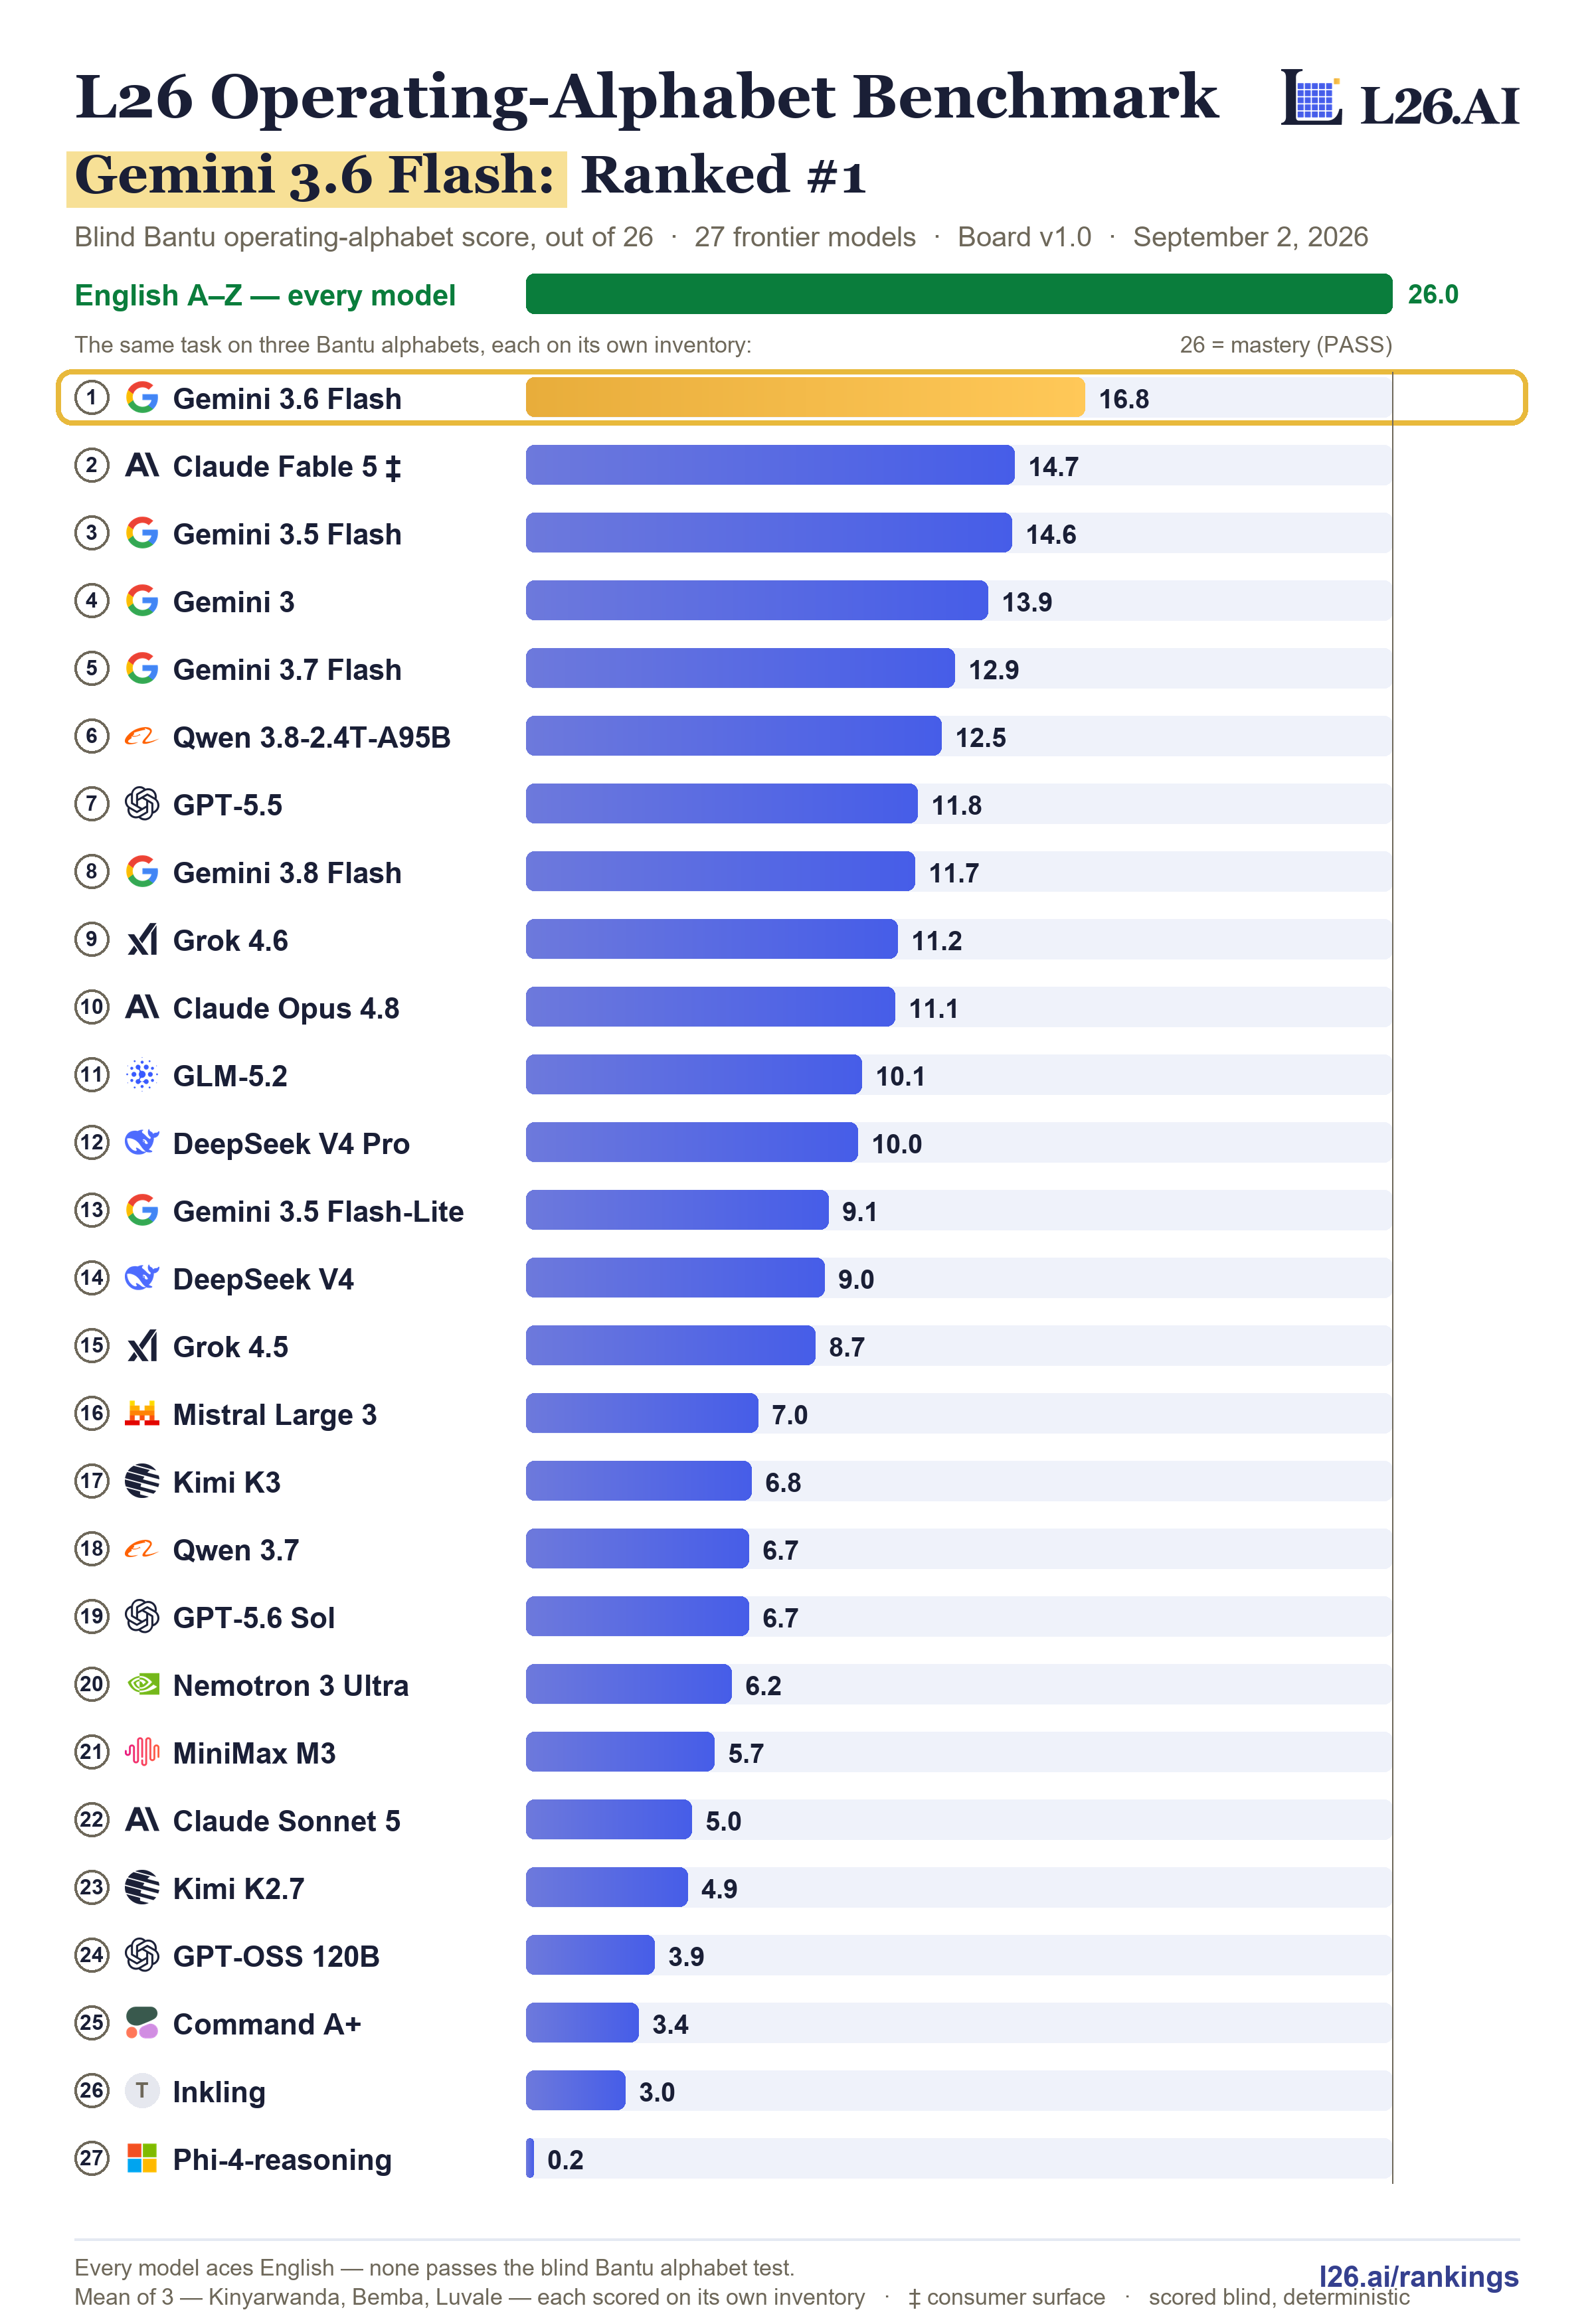
Gemini 3.6 Flash: Ranked #1

Blind Bantu operating-alphabet score, out of 26 · 27 frontier models · Board v1.0 · September 2, 2026
Share this:𝕏 PostLinkedInWhatsApp

ABC Test. The ABC Test is simple: complete means complete. Missing even one required unit—or inventing one that does not belong—means FAIL. Only a fully correct operating alphabet earns PASS. A model can rank #1 and still FAIL: the score out of 26 measures relative performance; PASS / FAIL is the strict completeness verdict.

English A–Z every model
26.0 / 26
The same task on three Bantu alphabets, each on its own inventory:26 = mastery (PASS)
RANK / MODELBLIND BANTU MEANABC TEST
1Gemini 3.6 FlashGoogle · Proprietary
16.8 / 26
FAIL↗
2Claude Fable 5 ‡Anthropic · Proprietary
14.7 / 26
FAIL↗
3Gemini 3.5 FlashGoogle · Proprietary
14.6 / 26
FAIL↗
4Gemini 3Google · Proprietary
13.9 / 26
FAIL↗
5Gemini 3.7 FlashGoogle · Proprietary
12.9 / 26
FAIL↗
6Qwen 3.8-2.4T-A95BAlibaba · Open
12.5 / 26
FAIL↗
7GPT-5.5OpenAI · Proprietary
11.8 / 26
FAIL↗
8Gemini 3.8 FlashGoogle · Proprietary
11.7 / 26
FAIL↗
9Grok 4.6SpaceXAI · Proprietary
11.2 / 26
FAIL↗
10Claude Opus 4.8Anthropic · Proprietary
11.1 / 26
FAIL↗
11GLM-5.2Z.ai / Zhipu · Open
10.1 / 26
FAIL↗
12DeepSeek V4 ProDeepSeek · Open
10.0 / 26
FAIL
13Gemini 3.5 Flash-LiteGoogle · Proprietary
9.1 / 26
FAIL↗
14DeepSeek V4DeepSeek · Open
9.0 / 26
FAIL↗
15Grok 4.5SpaceXAI · Proprietary
8.7 / 26
FAIL↗
16Mistral Large 3Mistral AI · Proprietary
7.0 / 26
FAIL↗
17Kimi K3Moonshot AI · Open
6.8 / 26
FAIL↗
18Qwen 3.7Alibaba · Open
6.7 / 26
FAIL↗
19GPT-5.6 SolOpenAI · Proprietary
6.7 / 26
FAIL↗
20Nemotron 3 UltraNVIDIA · Open
6.2 / 26
FAIL↗
21MiniMax M3MiniMax · Open
5.7 / 26
FAIL↗
22Claude Sonnet 5Anthropic · Proprietary
5.0 / 26
FAIL↗
23Kimi K2.7Moonshot AI · Open
4.9 / 26
FAIL↗
24GPT-OSS 120BOpenAI · Open
3.9 / 26
FAIL↗
25Command A+Cohere · Proprietary
3.4 / 26
FAIL↗
26InklingThinking Machines Lab · Open
3.0 / 26
FAIL↗
27Phi-4-reasoningMicrosoft · Open
0.2 / 26
FAIL↗
Every model aces English — none passes the blind Bantu alphabet test. Mean of 3 — Kinyarwanda, Bemba, Luvale — each scored on its own inventory; there is no single "Bantu" alphabet. ‡ consumer surface (API declined) · † declines annotated · ◊ label is the family, not the checkpoint · scored blind, 5 reps/cell, deterministic grading.

What this chart shows

L26 asks one foundation-level question: can a model list every building block a language is made from — its complete alphabet? For English that's the 26 letters; for Bantu languages it's the complete Native Syllable Inventory (Bemba, Kinyarwanda, Luvale). Scores are reported on the same 26-point scale — L26 = 26 × recall × precision — in the blind condition: the model is given nothing but the request. Every model above scores a perfect 26.0 on English. None comes close on the alphabets it has barely seen.

Explore the full leaderboard, read why this is the Hassabis–Einstein Test for language, or see the July 2026 frontier report.